



# Making Diffusion Language Models Lightning Fast: A New Approach to Speeding Up Text Generation
## The Problem with Slow Generation
Large language models have revolutionized how we interact with AI, but speed remains a major bottleneck. Traditional autoregressive models generate text one word at a time — each new token depends on the ones that came before it. This sequential process can feel sluggish, especially when running on consumer hardware.
A newer type of model, called a **diffusion language model (dLLM)**, takes a fundamentally different approach. Instead of generating tokens one by one, it processes multiple tokens simultaneously, refining them across several rounds of computation. Think of it like an artist making multiple passes over a sketch, gradually sharpening details with each pass, rather than drawing each line in sequence.
The challenge? These models often need many of those “passes” — called denoising steps — before they produce confident, accurate text. Each step costs computation time, so the speed advantage of parallel generation can be undermined if too many steps are required.
## A Fresh Take on Speeding Things Up
Researchers have introduced a novel training strategy that tackles this bottleneck head-on. The approach has two core innovations working together.
### Learning from Your Own Progress
The first idea centers on how the model learns to refine its predictions. Rather than training the model to produce final answers from a fixed starting point, the new method lets the model practice on the exact intermediate states it encounters when running on its own outputs during actual use.
Here’s why this matters: earlier approaches tried to replay old, pre-recorded intermediate states during training. But the model changes over time, so those old states no longer match what the model would actually produce during inference. It’s like rehearsing for a play using outdated scripts — the lines don’t match the current version of the performance.
By capturing fresh, real-time intermediate states generated by the current model and using those directly for training, the approach ensures the model learns to refine its outputs using the exact patterns it will encounter in practice. This eliminates the mismatch and leads to more efficient learning.
### Encouraging Faster Convergence
The second innovation addresses a subtler problem. Even if a model learns to produce correct outputs, it might still take many steps to get there — simply because the training signal didn’t explicitly reward faster convergence.
To fix this, the researchers introduced a training objective that encourages each computational step to meaningfully reduce uncertainty compared to the step before it. Think of it as giving the model a gold star every time it makes a noticeable commitment to a word, rather than just waiting until the final output to measure success. A gating mechanism ensures the model doesn’t waste effort on decisions it has already confidently made, keeping the training signal focused and efficient.
Together, these two techniques teach the model to finalize more tokens in fewer steps, dramatically improving throughput without sacrificing the quality of the output.
## The Inference Engine That Makes It All Click
Training improvements alone aren’t enough. The researchers also built a custom inference engine designed specifically for low-latency, single-request decoding with diffusion models.
The key technical trick here involves **CUDA graphs** — a feature that allows an entire sequence of GPU operations to be recorded and replayed as a single, unified package. Normally, each denoising step requires launching it separately from the CPU, which introduces synchronization overhead and idle time. By capturing the full loop of denoising steps into one CUDA graph, the engine eliminates this overhead and keeps the GPU fully utilized throughout the entire generation process.
The engine also supports highly compressed numerical precision (4-bit formats) on modern GPU architectures, including consumer-grade hardware. This means impressive speeds are achievable without requiring expensive, specialized data-center cards.
In head-to-head comparisons with established systems, the custom engine runs measurably faster than popular alternatives, delivering a meaningful speed boost even when using identical models and decoding settings.
## Impressive Results on Real Models
The approach was tested across several different model families, demonstrating broad applicability.
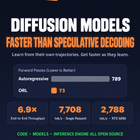
– On one compact 4-billion-parameter model converted to a diffusion architecture, the strategy delivered up to a **six-fold improvement** in the number of tokens finalized per computational step and nearly a **seven-fold increase** in overall end-to-end speed. Notably, the model also scored higher on coding tasks after the optimization, improving from strong to excellent.
– On a smaller model, the method achieved up to **three times the throughput** using only a modest amount of self-generated training data and a limited number of GPU-hours for post-training — making it practical even for smaller research teams.
– On a larger, more powerful model with a mixture-of-experts architecture, the approach still provided additional gains, squeezing more efficiency out of an already highly parallel system.
In a direct comparison with autoregressive-style acceleration techniques, the optimized model on a single high-end GPU delivered more than double the token generation speed while maintaining comparable accuracy.
## Fully Open Source
Everything — the training code, evaluation tools, the inference engine, and the model checkpoints — has been made freely available. This means anyone with compatible hardware can reproduce the results, experiment with the models, or contribute improvements to the inference engine. The researchers have specifically invited community feedback, encouraging users to test the systems under different workloads and share their findings.
—
## Frequently Asked Questions
**What exactly is a diffusion language model?**
A diffusion language model generates text by starting with noisy, random tokens and progressively refining them over multiple steps — similar to how a diffusion image model starts with noise and gradually produces a clear picture. The result is that many tokens can be refined in parallel, rather than one at a time.
**Why does faster generation matter?**
Faster generation means lower latency, which improves the user experience for real-time applications like chatbots, coding assistants, and interactive tools. It also reduces computing costs, since fewer GPU resources are consumed per request.
**Can I run these models on consumer hardware?**
Yes. The models and inference engine are optimized to run on consumer-grade GPUs, including the NVIDIA RTX 5090, using compressed precision formats that reduce memory usage and increase speed.
**Does sacrificing speed affect the quality of the output?**
No. The training strategy was specifically designed to maintain or even improve generation quality while increasing speed. Benchmark results show that accuracy metrics either held steady or improved alongside the throughput gains.
**Is the inference engine only useful for diffusion models?**
The inference engine was built with diffusion language models in mind, but its CUDA graph optimization techniques for capturing and replaying GPU operations can be applied more broadly to other sequential GPU workloads.
**What’s the difference between this and speculative decoding?**
Speculative decoding is a technique used with autoregressive models where a small model proposes multiple tokens quickly, and a larger model verifies them. This approach is fundamentally different because it works at the training level to teach a diffusion model to converge in fewer steps, rather than parallelizing verification across a draft-and-verify pipeline.
—
## Conclusion
Speed has long been a limiting factor for diffusion language models, but this new training strategy and accompanying inference engine change the equation. By training models on their own real-time intermediate states and encouraging faster convergence through targeted uncertainty reduction, the approach teaches diffusion models to produce confident text in dramatically fewer steps. Paired with a custom inference engine that keeps the GPU working at full capacity, the result is a system that delivers significantly higher throughput without sacrificing — and in some cases improving — output quality.
The full open-source release invites the entire community to build on this work, experiment with new models and workloads, and push the boundaries of what’s possible with diffusion language models on everyday hardware. The intersection of fast generation and open access is an exciting step forward for the field.
Thank you for reading
