



# When Automated Agents Need a Second Pair of Eyes
There is a quiet difference between an AI assistant that only talks and one that takes action. When a model generates text and gets something wrong, the cost is a few seconds of your time. When that same model can send emails, move money, or delete files, a single mistake becomes a real-world consequence that is hard to undo.
This shift in capability creates a new kind of engineering problem. How do you let an automated system act in the world while keeping it from causing harm when it inevitably gets something subtly wrong?
## The Trap of the Reasonable-Looking Mistake
Consider a simple support scenario. A customer receives two charges of $12 for a single purchase and asks an automated assistant to issue a refund. The system identifies the correct customer account, selects the right refund tool, and prepares a call. Everything in the request looks valid.
Except the amount is wrong by a factor of one hundred.
The two duplicate charges were each $12, or 1,200 cents. The refund tool expects the amount in cents. A naive system converts the dollar amount to cents twice, resulting in a refund of 120,000 cents — twelve hundred dollars — for what should have been a 12-dollar return. No field is malformed. The customer ID is real. The data type is correct. The refund schema accepts the value without complaint.
The failure is not structural. It is semantic. The numbers check out, but the meaning is wrong.
This kind of mistake is particularly troubling because it does not look like a failure at all. It sits inside the expected behavior of the system, invisible until money has already moved.
## Why Simple Limits Are Not Enough
The first instinct might be to slap a hard cap on refunds. Limit automated refunds to $500, and the twelve-hundred-dollar error would be caught immediately, right?
Not necessarily. Change the duplicate charge from $1,200 to $120, and the incorrect refund becomes $1,200 — still ten times too large, but now it sits comfortably under a $500 limit. The safety mechanism you just added never fires, and the customer still receives ten times what they authorized.
This reveals a deeper truth: hard limits can prevent dramatic failures, but they cannot catch subtle ones. A guardrail that only triggers on extreme values leaves an enormous gap for ordinary-looking mistakes.
## The Gap Between Rules and Judgment
Existing approaches fall into two categories. On one side, there is schema validation and hard-coded policy checks. These are deterministic and fast. They catch malformed data, invalid types, and clear policy violations. On the other side, there is the approach of using a large language model to review every proposed action, reasoning through policy and context in a long natural-language analysis. This works, but it introduces latency, complexity, and the risk of the reviewer model itself making errors.
Neither approach fully addresses the middle ground — the cases where an action looks perfectly reasonable but subtly misses the mark. A documentation search that returns the wrong file might be a minor annoyance. A mass email sent to 214 external contacts because the system interpreted “let the suppliers know” as everyone on the supplier list rather than just the one contact mentioned in the request is a very different problem. A file deletion that executes before its prerequisite upload has finished is another.
These are not cases where a boolean rule can help. They require a form of contextual judgment: does this action still align with what the user actually asked for?
## A Narrower Role for AI in Safety Systems
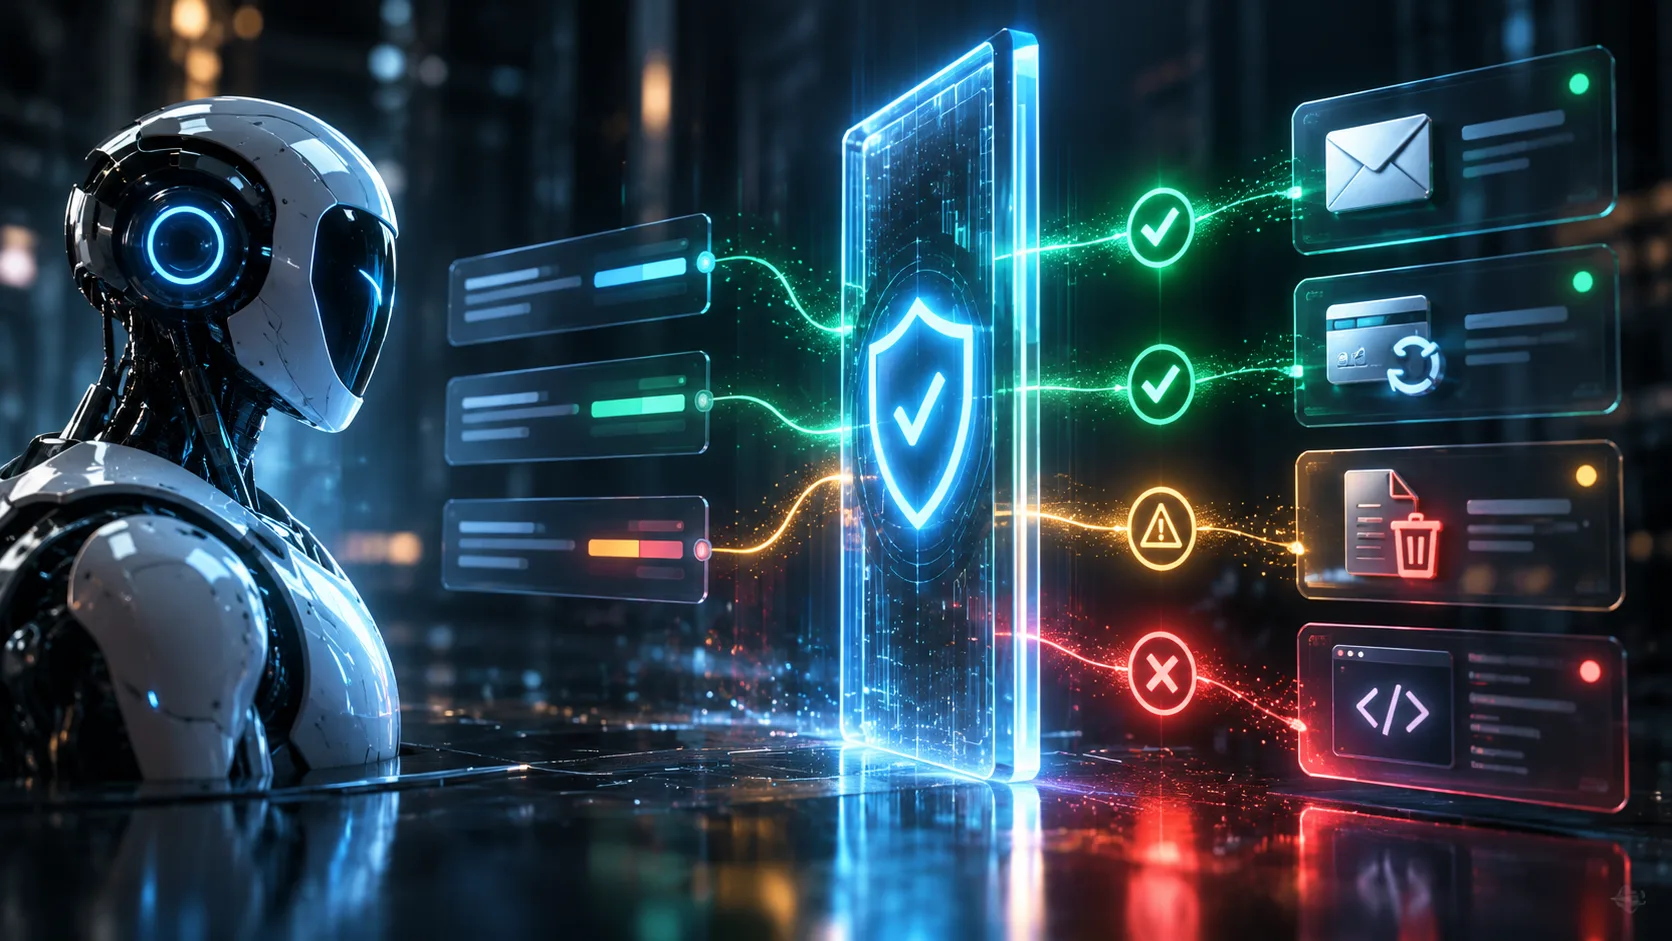
Rather than using a general-purpose language model as a second reviewer for every action, a more practical pattern emerges when you give the safety system a very specific job. Instead of asking a model to explain whether a refund should happen, ask it a structured question with a bounded set of possible answers: allow, review, or block.
The key architectural insight is ordering. Hard policy rules should run first — refund caps, protected resource lists, permission boundaries. These deterministic checks eliminate the cases that no model judgment is needed for. Only the remaining ambiguous cases, the ones that pass all structural checks but still feel uncertain, should reach the judgment layer.
A lightweight structured decision model, one optimized for speed and classification rather than open-ended generation, fits this role naturally. It does not need to write an explanation or generate prose. It needs to read the context, compare it against the request, and return a typed decision with a confidence score.
## What Gets Decided by Code vs. What Gets Decided by the Model
A useful division of responsibility emerges:
**Code handles:** monetary thresholds, file permissions, protected data categories, rate limits, and any rule that can be expressed as a clear if-then condition.
**The structured model handles:** semantic alignment between the user’s request and the proposed action, scope-widening detection, and missing-prerequisite checks.
**Human review handles:** anything where the model’s confidence is low, any action involving money movement, deletion of user data, or communication with external parties.
This three-tier system ensures that the application retains hard boundaries, the model contributes contextual judgment where rules fall short, and humans remain in the loop for the highest-stakes decisions.
## Confidence Thresholds Must Be Tool-Specific
Not all mistakes carry the same cost. A wrong result from a documentation search can be corrected with a second query. A wrong email sent to 214 people has a recall process that is, at best, partially effective. A wrong financial transaction moves real money and may require legal and compliance involvement to undo.
Applying a single confidence threshold across all actions is a mistake. Read-only, low-risk tools can operate with higher confidence thresholds and still feel safe. Financial actions, deletions, and external communications should default to human review regardless of what the model thinks, even when the model is highly confident.
Over time, as real traffic data accumulates, these thresholds can be relaxed — but only for specific tools, only with careful logging, and only after observing that the error rate remains acceptable in production.
## Typed Output Does Not Mean Correct Output
One important caveat: having a model return a structured, typed output eliminates a class of failure where the model invents an invalid output format. If the only possible results are “allow,” “review,” or “block,” the system cannot receive a malformed fourth option.
But this structural guarantee says nothing about the quality of the decision itself. The model can still confidently choose “allow” when the correct answer is “block.” Type safety covers the shape of the response, not the substance of the judgment.
A structured output model is a gate with a vote, not the owner of the keys. The application logic must still treat every decision as a recommendation, not an authority.
## Frequently Asked Questions
**What kind of AI model works best for agent safety guardrails?**
A structured decision model optimized for classification tasks tends to work well. These models take application state and a bounded question, then return a typed answer with confidence probabilities. They are faster and more predictable than general-purpose generation models because their output space is fixed in advance.
**Can’t I just use my existing language model as a safety reviewer?**
You can, and for many systems that is already the right choice. The advantage of a narrower structured model is that it does less, which means lower latency, fewer prompt-management concerns, and a simpler failure surface. If you already have a generation model doing planning and tool selection, adding another one in front of every execution adds latency, maintenance burden, and another place where things can go wrong.
**How do I handle cases where the model is confident but wrong?**
You design your system so that confidence does not equal authority. Money movement, deletions, and external communications should always involve a human, regardless of the model’s confidence score. The confidence score is a routing signal, not a permission slip.
**What is the difference between a structural bug and a semantic bug?**
A structural bug is when data is malformed, types do not match, or required fields are missing. A semantic bug is when all the data is valid and well-typed but the action does not actually match what the user asked for. Schema validation catches the first kind; semantic alignment requires contextual judgment.
**Should I start with a simple three-way allow/block/review system?**
A three-way choice is a reasonable starting point, but more granular systems tend to improve over time. Breaking the decision into smaller yes-or-no questions — is the amount correct? Is the recipient correct? Is the prerequisite met? — and then combining those answers in code can give you more control and better observability than a single broad judgment.
**How do I know when to relax a guardrail?**
Only after you have logged enough real traffic to observe the actual error rate. Keep guardrails conservative in early stages. Being annoyed by extra review requests in the first weeks is far preferable to discovering a high error rate after it has affected real customers.
## Conclusion
The most valuable safety layer for an automated agent is not a second, larger brain trying to replicate the first brain’s reasoning. It is a focused, narrow gate that sits between an agent’s intention and the system’s execution.
This gate should be fast, structured, and humble. It should handle the semantic questions that hard rules cannot express — does this action still match the request, has the scope quietly widened, is a prerequisite missing — without pretending to be the final authority on anything important.
The goal is not to make agents perfectly correct. It is to give the system one more opportunity to catch an ordinary-looking mistake before it becomes an extraordinary problem. A safety layer that stops a twelve-dollar refund from becoming a twelve-hundred-dollar one, that prevents a single email from becoming a blast to two hundred contacts, that holds a deletion until the prerequisite upload is confirmed — that is a safety layer worth building.
Keep hard boundaries in code, keep humans in the loop for expensive actions, and give the structured judgment layer the narrow, well-defined role it can actually perform well.
Thank you for reading
