



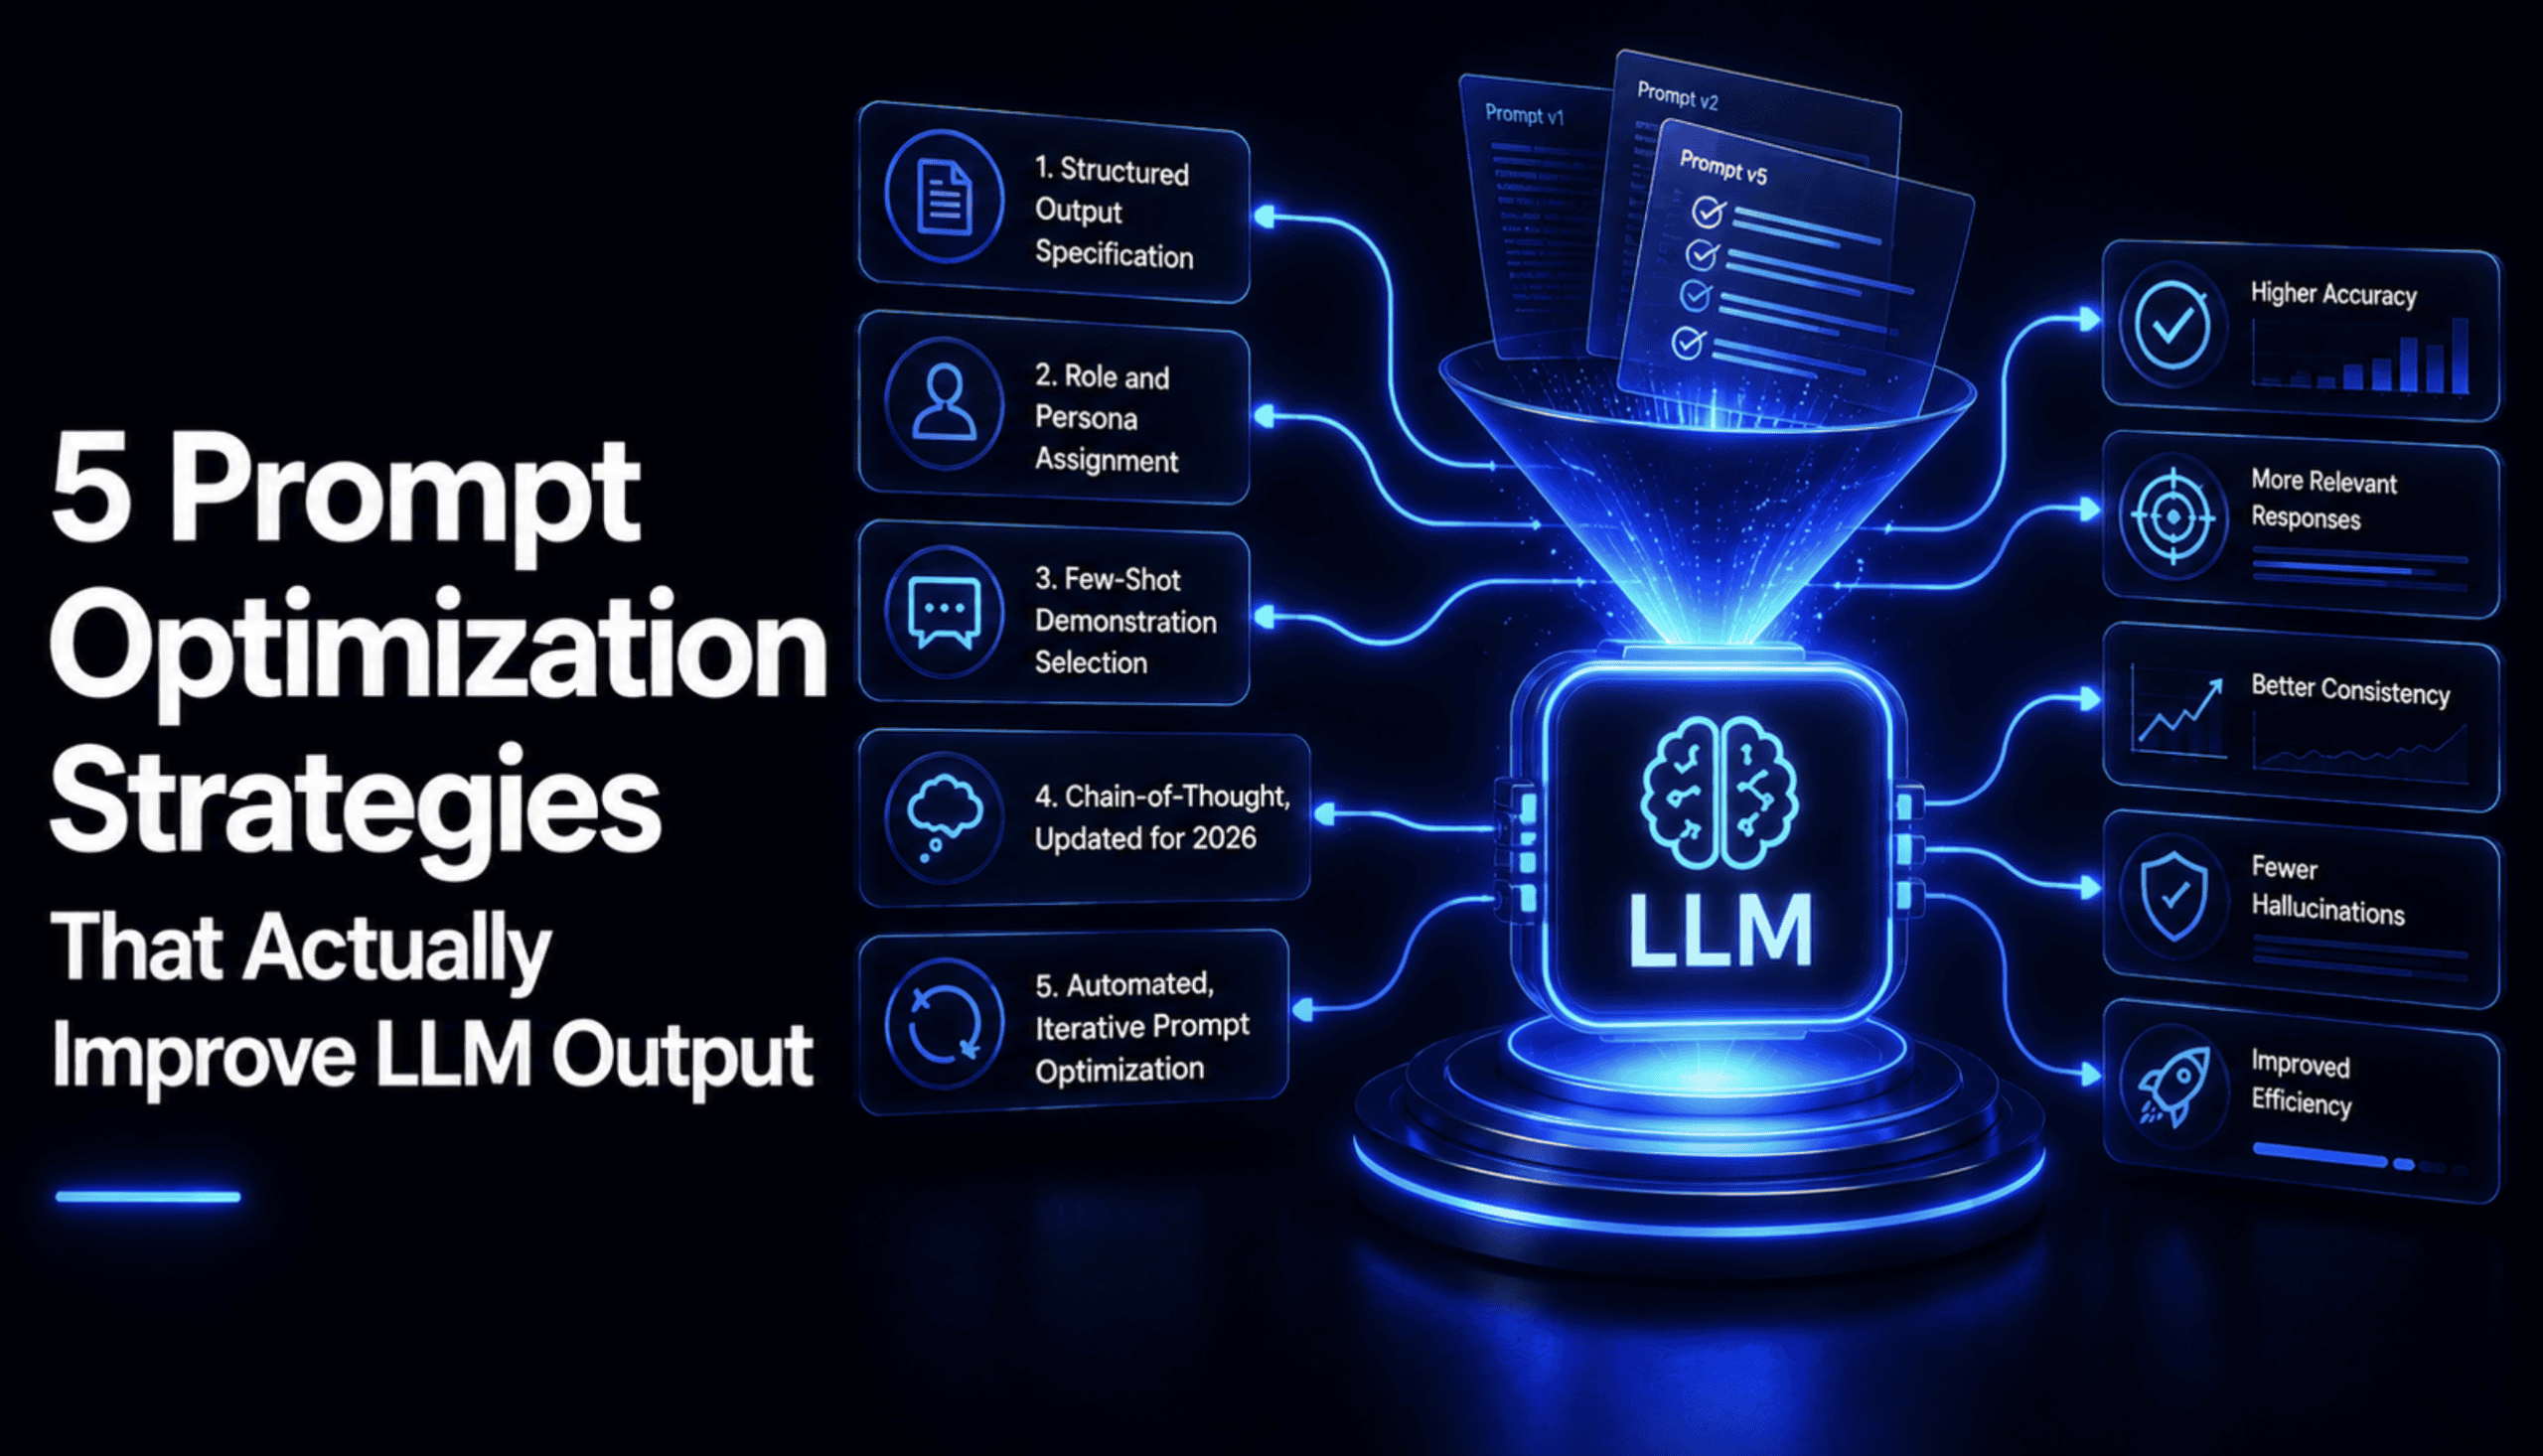
# How to Actually Improve LLM Outputs: Five Prompt Optimization Strategies That Make a Measurable Difference
Prompt engineering and prompt optimization are frequently treated as the same discipline, but they serve fundamentally different purposes. Engineering involves creating a prompt from nothing, while optimization means refining an existing prompt — tightening specificity, improving structure, and iterating — without altering the underlying model. This distinction matters because most practitioners who ask how to get better results from a large language model already have a functional prompt. What they truly need is to understand which specific, targeted adjustments to an existing prompt produce real improvements and which changes only feel productive.
Throughout this piece, every strategy is demonstrated against the same deliberately imperfect meeting transcript, where the correct output is already known and can be used as a benchmark. The transcript features three speakers, mid-conversation reassignments, merged tasks, and one explicitly unresolved ownership — the kind of genuine messiness that separates surface-level success from reliable accuracy.
—
## The Challenge of Working with Messy Real-World Inputs
Consider a meeting transcript where mobile UI review ownership shifts mid-discussion, a tablet-breakpoint check gets folded into an existing task rather than creating a separate one, and triage responsibility for a growing support queue is deliberately left without an assigned owner. A prompt that correctly captures the straightforward elements but mishandles these three nuanced details isn’t genuinely working — it only appears to be at a glance. Many production failures trace back to precisely this gap: outputs that look plausible but contain subtle errors that downstream consumers eventually discover the hard way.
—
## Strategy 1: Define a Clear Output Schema Before Anything Else
The most immediate and measurable improvement available is specifying the exact structure the model’s response should follow. Asking a model to “list the action items” produces fluent prose that no automated system can reliably consume. Unparseable output isn’t a cosmetic inconvenience — in production environments, it’s a hard failure that requires manual human intervention.
Using a validation framework like Pydantic, it’s possible to define a strict schema for each action item, including fields for the assigned owner, the task description, and the expected deadline. When a model returns freeform prose, the validator correctly rejects it, preventing a partial or misleading result from flowing silently into a database or a task-tracking system. When the same information is requested with an explicit JSON schema that the model can follow, the response parses cleanly into structured, validated objects.
The takeaway here is straightforward: structured output transforms a response from something a human must manually re-read and transcribe into something a program can actually use. This single adjustment often resolves the most common class of prompt-related failures before any other strategy is even applied.
—
## Strategy 2: Prime the Model with a Specific Role and Persona
Assigning a well-defined role changes which capabilities the model activates for a given task, producing more structured and context-aware responses than a bare instruction ever could. It’s a minimal change with measurable impact, and it requires no additional infrastructure to test.
A generic instruction like “Extract the action items from this meeting transcript” gives the model no reason to pay special attention to ownership reassignments or unresolved assignments. A role-based prompt, by contrast, establishes expectations upfront — describing a persona that has seen hundreds of similar meetings and knows that people frequently change their minds mid-sentence, that assignments get transferred between participants, and that a reliable note-taker never invents an owner who wasn’t explicitly confirmed.
When facing a transcript with this level of ambiguity, the role-based prompt preconditions the model to anticipate exactly these kinds of edge cases before it begins processing the content. The effect is most pronounced on inputs messy enough that a careless first pass would naturally miss the nuance — which is precisely the scenario worth optimizing for.
—
## Strategy 3: Curate Demonstrations for Maximum Variety, Not Maximum Volume
Research into few-shot prompting has revealed an insight that often gets overlooked in practice: demonstration selection can matter more than the instruction wording itself, and deliberately combining strong examples with well-chosen instructions outperforms either approach alone. The critical nuance is that it isn’t simply about adding examples — it’s about which examples are added.
A set of demonstrations that accidentally contains multiple near-duplicates of the same pattern teaches the model very little it hasn’t already absorbed. Using similarity-based selection methods, it’s possible to identify and remove redundant examples from a candidate pool, replacing them with illustrations of genuinely different scenarios.
For the transcript task, the ideal few-shot set should include an example with a confirmed owner, an example where ownership is explicitly left unresolved, and an example where a task gets absorbed into an earlier item rather than being treated as a separate entry. These three distinct patterns — confirmed ownership, ambiguous ownership, and task merging — represent the actual failure modes the prompt needs to handle, not three variations on the simplest possible case.
—
## Strategy 4: Use Step-by-Step Reasoning on Genuinely Ambiguous Cases
Chain-of-thought prompting — asking the model to reason through its answer before committing to a final result — remains a valuable tool, though its importance has evolved alongside model capability. Modern frontier models reason internally with increasing sophistication, which means explicitly requesting step-by-step reasoning provides diminishing returns for straightforward tasks where it was originally most dramatic.
However, it earns its place on inputs with real ambiguity. In the transcript, the mobile review ownership creates exactly this kind of trap: an initial assignment followed by a correction two lines later. Without a reasoning step, the model can latch onto the first plausible assignment and carry it forward. With a reasoning prompt that explicitly directs the model to trace ownership across the entire conversation and report only the final confirmed holder, the error becomes far less likely.
For teams managing token costs, a compressed variant of this approach exists. Known as chain-of-draft, it asks the model to distill each reasoning step into roughly five words rather than full sentences. Published research indicates it can achieve comparable accuracy to standard chain-of-thought while consuming a fraction of the tokens, making it a practical option once reasoning is confirmed to be beneficial and cost optimization becomes a priority.
—
## Strategy 5: Let Automated Iteration Replace Manual Guessing
The most sophisticated strategy on this list transforms prompt refinement from an art into a science. Rather than relying on intuition to decide which wording changes to try, candidate prompts are scored against real test cases and a search process identifies the modifications that genuinely move the needle.
The process works by maintaining a base prompt and a library of potential instruction fragments. At each iteration, a new fragment is appended, the resulting prompt is scored against known-correct answers, and the best-performing combination is kept. Scoring evaluates multiple dimensions simultaneously: whether all correct items were found, whether owners were attributed accurately, and whether any fabricated items appeared in the output. Fabrication carries a significant penalty because an incorrect result that looks complete is arguably worse than an incomplete result that’s clearly labeled as uncertain.
When applied to the transcript starting from a bare minimum instruction, this iterative approach rapidly converges on the essential fixes — tracking final ownership, avoiding invented assignees, and filtering out non-action discussion — while ignoring fragments that don’t contribute. In a test run, the process reached a perfect score after discovering just three of the five available fragments, demonstrating that the minimum effective fix is often far smaller than what an experienced human might guess at.
—
## Common Questions About Prompt Optimization
**Isn’t prompt engineering enough on its own?**
Prompt engineering is essential for getting started, but it addresses the blank-page problem. Once a working prompt exists, optimization — the systematic refinement of that prompt through structured testing — is what separates outputs that merely seem correct from outputs that are provably correct against known benchmarks.
**Do these strategies work equally well for every type of LLM task?**
The strategies here were demonstrated on a structured extraction task from unstructured text. Structured output validation applies broadly. Role assignment tends to benefit tasks requiring careful attention to nuance. Demonstration curation is most impactful on tasks with varied input patterns. Chain-of-thought reasoning shines on ambiguous or multi-step problems. Automated optimization is most valuable once hand-tuning has reached its limits and a measurable feedback loop exists.
**How many few-shot examples do I actually need?**
Quality matters far more than quantity. Three deliberately diverse examples covering distinct patterns typically outperform ten near-identical ones. The goal is coverage of the failure modes the model is likely to encounter, not volume of training data.
**Is chain-of-thought always worth the extra tokens?**
No. For simple, well-defined tasks, it adds cost and latency without meaningful accuracy gains. Reserve it for genuinely ambiguous inputs where the model has clear incentive to pattern-match incorrectly on a first read, and consider the compressed chain-of-draft variant when cost is a concern.
**What’s the biggest mistake teams make when trying to improve prompts?**
The most common mistake is changing multiple things simultaneously and not knowing which change actually caused the improvement. Each strategy should be tested in isolation, scored against a ground-truth benchmark, and only combined once its individual contribution is confirmed.
—
## Conclusion
The five strategies explored here — structured output schemas, role assignment, curated few-shot demonstrations, targeted chain-of-thought reasoning, and automated iterative optimization — collectively represent a disciplined approach to getting reliable LLM outputs. The unifying principle behind all of them is simple: replace guesswork with measurement. If an output looks reasonable but fails to parse, resolve the schema first. If results shift unpredictably based on phrasing, invest in better demonstrations. If the model misses errors a careful reader would catch, apply reasoning specifically to those failure modes. And when manual tuning reaches a ceiling, automated scoring-based search finds the precise fixes that intuition alone would overlook.
Prompt optimization isn’t about making prompts longer or more elaborate. It’s about making each word count, backed by evidence from real cases and real failure modes. Starting with any one of these strategies and layering in the others as problems surface is a practical path toward outputs that are not just plausible, but provably correct.
Thank you for reading
