



# Beyond Text Generation: Rethinking How AI Systems Make Bounded Decisions
## The Hidden Choice Inside Your Agentic Pipeline
When most people think about what language models do, they picture a system that generates text one word at a time — a next-token prediction engine. That framing is accurate for many use cases, but it misses a critical truth: not every invocation of an AI model needs to produce a paragraph, a code block, or a reasoning trace. Many operations inside modern agentic systems are narrow, bounded decisions — and treating them as text-generation tasks introduces unnecessary cost, latency, and measurement difficulty.
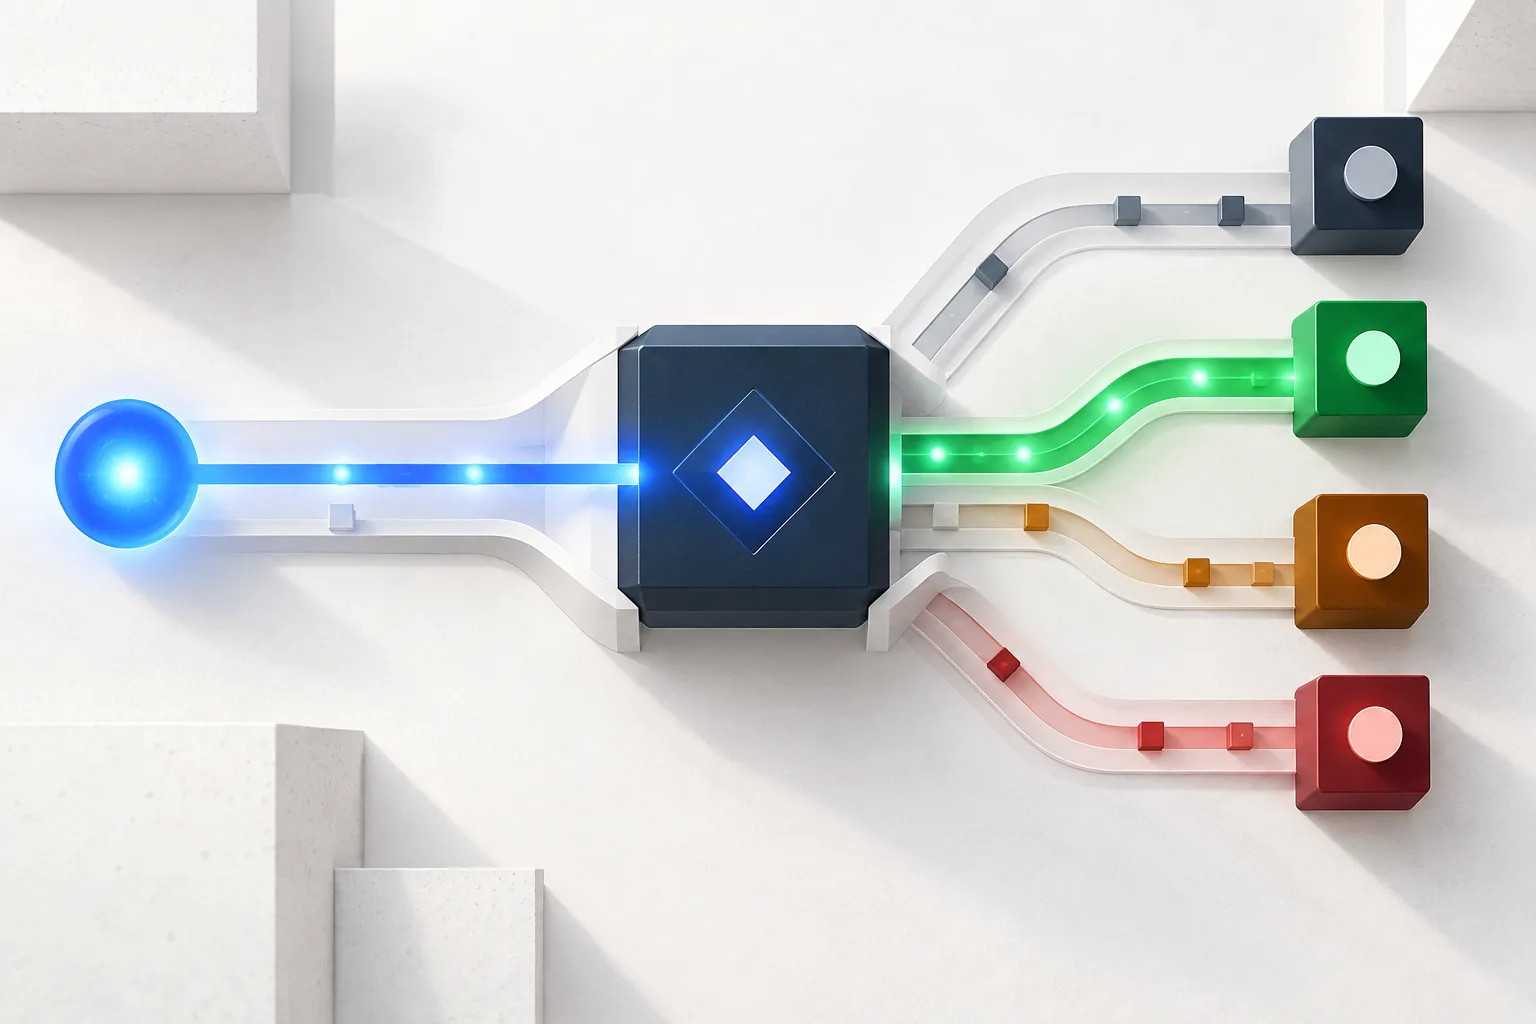
This article explores the architectural shift from implicit, generation-based routing toward an explicit decision layer that treats routing as a classification-shaped problem with measurable outcomes.
—
## The Agentic Stack Is Actually Three Separate Problems
Agentic AI systems are frequently marketed as monolithic intelligence engines, but well-designed production architectures decompose the work into at least three distinct layers:
– **Planner:** Breaks a high-level goal into intermediate steps or sub-tasks, often relying on broad generative reasoning.
– **Orchestrator:** Manages state, sequencing, retries, and handoffs between components using deterministic logic.
– **Router:** Selects which tool, specialist, or handling path a given request should follow.
The router is where the opportunity lives. Consider a typical support system that must decide whether an incoming request should be handled by a retrieval agent, a billing specialist, a security reviewer, or escalated to a human. That is not a request for creative prose. It is a bounded choice among a known set of options.
Yet most current architectures pass this decision through the same autoregressive decoder used for open-ended text generation — adding prompt engineering, structured output constraints, parsing, schema validation, and retry logic on top of what is fundamentally a classification task.
—
## Why Autoregressive Routing Is Convenient but Suboptimal
The dominant pattern works like this: a request and system context are fed into a decoder language model alongside a catalog of available routes. The model emits a label, a JSON object, or a function call. The surrounding software then parses that output, validates it against an expected schema, retries if the format is malformed, and finally invokes the selected component.
This pattern has genuine strengths. A general-purpose decoder can interpret policies written in natural language, handle unusual edge cases gracefully, and explain its reasoning to a human operator. It also adapts easily when new routes are introduced — you simply update the prompt.
But the flexibility comes at a price. Autoregressive decoding is inherently sequential: each token depends on all preceding tokens, making efficient batch processing difficult. A routing decision that could be expressed as a single score per candidate instead gets wrapped in token-by-token generation, prompt assembly, output parsing, and validation logic. The total cost and latency of the route are far greater than the cost of the decision itself.
—
## When Generation-Based Routing Makes Sense
There are real scenarios where letting a decoder handle routing is the right call:
– The action space is open-ended or changes so frequently that maintaining a stable candidate set is impractical.
– The route must include generated reasoning, arguments, or a multi-step execution plan alongside the label.
– The system requires deep language understanding before the decision categories can even be defined.
– The workflow volume is low enough that the engineering cost of a specialized decision component is not justified.
In these cases, the decoder’s flexibility is a feature, not a liability. The key insight is recognizing when the task genuinely requires generation and when it is really just a selection problem in disguise.
—
## The Classical Baseline That Deserves a Second Look
Before the era of large decoder models, text classification was solved with encoder architectures — models like BERT that map an input into a contextual representation and then score each predefined label independently. The mathematical formulation is straightforward: given an input and a set of allowed labels, produce a score for each one, then select the highest or apply a confidence threshold.
This approach has a well-known limitation: the label set must be fixed at training time. Adding new classes requires retraining or at least extending the output head. But for stable, high-volume routing problems with a well-defined taxonomy, encoder-plus-head classification remains efficient, compact, and easy to evaluate.
A proper routing system should be able to compare a decoder-based approach against a classifier baseline on the exact same data, routes, and evaluation criteria. The winner depends on the workload — and the comparison should measure more than just top-1 accuracy.
—
## The Decision Layer: A New System Primitive
The central proposal here is not that everyone should abandon decoder models. It is that bounded routing decisions deserve their own architectural primitive — a decision layer designed explicitly for selection over candidate sets.
A decision layer does the following:
1. Receives an explicit list of candidate routes alongside the current request and system state.
2. Produces typed scores or probabilities for each candidate.
3. Applies a configurable policy — automatically route above a confidence threshold, require a margin between top candidates, or abstain when uncertainty is too high.
4. Returns a deterministic result that downstream software can consume without parsing, validation, or repair.
This transforms routing from a hidden behavior of a prompt into a measurable software contract. Teams can log candidate sets, scores, policy versions, selected routes, and outcomes. They can evaluate calibration, latency, cost, and downstream workflow success with the same rigor applied to any other production component.
Abstention is a first-class feature, not an error condition. By choosing to automate only high-confidence decisions and routing ambiguous cases to slower planners or human reviewers, a system can improve the quality of its automated actions even when raw model accuracy remains unchanged. The trade-off between coverage and risk becomes explicit and tunable.
—
## What a Measurement-First Comparison Looks Like
Any serious evaluation of routing approaches should compare at least three configurations on identical data:
– A decoder LLM with structured output validation and retry logic.
– An encoder-based classifier with a fixed label set.
– A structured decision interface with explicit candidates, scores, and an abstention policy.
Beyond accuracy, the evaluation should report:
– **Route quality:** Macro-F1 scores, confusion matrices, and the real-world cost of misrouting.
– **Uncertainty quality:** Calibration curves, probabilistic scoring metrics, and how selective automation at different confidence thresholds affects outcomes.
– **Operational metrics:** Latency percentiles, cost per decision, retry and validation failure rates, and fallback frequency.
– **Robustness:** Behavior under distribution shift, new or retired routes, adversarial inputs, and ambiguous cases.
The results will vary by domain. A decoder may excel when decisions require generative reasoning. A fixed classifier may dominate for stable, high-volume labels. A structured decision layer may offer the best balance when the system needs semantic flexibility but must present results as reliable, typed software inputs.
—
## Making Every Model Call Earn Its Place
The overarching argument is about resource allocation in agentic systems. Generation is expensive. When a decision can be expressed as a bounded selection among known candidates, it should not consume the same infrastructure as open-ended text creation.
The practical path forward is to make every routing decision visible: define the candidates, score them, state the conditions under which the system may act, state when it must abstain, and then measure the outcomes. This does not require replacing decoder models everywhere — it requires reserving their generative capacity for the steps where generation is genuinely needed.
Structured decision interfaces represent a meaningful architectural direction for AI systems: not magic routing, and not a reason to discard classical classification, but a more disciplined way to allocate intelligence across the agentic stack.
—
## Frequently Asked Questions
**What is a decision layer in the context of AI routing?**
A decision layer is an architectural component that treats bounded routing choices as a structured selection problem rather than an open-ended text generation task. It takes an explicit candidate set, returns typed scores for each option, and applies a confidence or abstention policy before handing the result to deterministic software.
**Why not just use a regular language model for routing?**
Language models can classify, and they offer flexibility for open-ended or rapidly changing policies. The issue is efficiency and measurability. A decoder must generate tokens sequentially, requiring parsing, validation, and often retry logic for a decision that could otherwise be a single structured output. For stable, finite route sets, this overhead is unnecessary.
**What makes the decision-layer approach different from a standard classifier?**
Classical classifiers require a fixed label set defined at training time. A decision layer can accept a caller-supplied candidate set at inference time, making it more adaptable to workflows where the available actions change. It also emphasizes uncertainty quantification and abstention policies as first-class features.
**Is abstention really a feature?**
Yes. Selective prediction lets a system automate only the cases it is confident about, routing uncertain requests to slower fallback paths. This improves the quality of automated actions and makes the coverage-risk trade-off measurable and tunable.
**Does this mean encoder classifiers are obsolete?**
No. For stable, high-volume routing with a fixed taxonomy, encoder-based classifiers remain an excellent choice. The point is that agentic systems should use the right tool for each step — generative models for planning and language tasks, structured decision components for bounded routing.
**How should teams evaluate which routing approach works best?**
Compare approaches on the same requests, route definitions, downstream tools, and fallback policies. Measure accuracy, calibration, latency, cost, retry rates, and robustness to policy changes or distribution shift. The best choice depends on the specific workflow.
**What is the relationship between generation and routing in a modern agentic system?**
They serve different purposes. Generation excels at open-ended reasoning, explanation, and interaction. Routing is a bounded selection problem. The most efficient systems allocate generative capacity to tasks that genuinely need it and use simpler, faster decision components for repeated bounded choices.
—
## Conclusion
The AI industry has spent enormous effort making language models better at generating text. That progress is real and valuable. But inside production agentic systems, a large fraction of model calls are not requests for prose — they are decisions between a finite set of known actions.
Treating every routing task as a generation problem is an architectural choice, not an inevitability. By introducing explicit decision layers that score candidates, communicate uncertainty, and integrate deterministically with software, teams can build systems that are faster, cheaper, easier to measure, and safer in production.
The path forward is not to abandon generative models. It is to stop using them for jobs they were not designed to do efficiently — and to give bounded decisions the structured, measurable interface they deserve.
Thank you for reading
