



# Compiling Natural Language into Self-Contained Neural Programs: A New Frontier in Local AI Execution
## Introduction
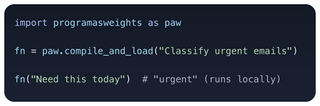
The landscape of artificial intelligence is shifting rapidly from cloud-dependent API calls toward models that can run entirely on local hardware, including modest CPUs. A fascinating new approach emerging from academic research seeks to bridge the gap between high-level human instructions and lightweight, portable neural functions. The concept is deceptively simple: you describe what you want a program to do in plain English, and the system produces a compact, reusable neural program that executes locally, without any need for an internet connection or external API after the initial setup.
This article explores how this paradigm works, why it matters, and what it could mean for the future of software development and AI deployment.
## The Core Problem: Reusable Intelligence for Repetitive Tasks
Many real-world applications involve a fixed logic applied repeatedly to changing data. Think of classifying incoming emails by urgency, extracting structured fields from unstructured documents, converting between data formats, or parsing log files for anomalies. In each case, the rule or judgment criteria remain constant — it is only the input that changes.
Traditionally, there have been two ways to handle this with large language models:
1. **Prompt the model every time** — which requires a network call, incurs latency, and creates ongoing dependency on external infrastructure.
2. **Hand-code a solution** — which is brittle, requires deep technical expertise, and struggles with ambiguous or fuzzy inputs.
Neither option is ideal. The first is expensive and slow at scale. The second is inflexible and error-prone when dealing with nuanced language.
## A New Paradigm: Separate Understanding from Execution
The key insight behind this new approach is to split the problem into two distinct phases.
**Phase one — compilation** — involves understanding a high-level natural language specification and translating it into a set of task-specific neural weights. Think of this as the “think once” step, where a larger, more capable model analyzes what you want and figures out how to encode that knowledge into a compact format.
**Phase two — inference** — is the repeated execution step. A much smaller model, carrying the specialized weights from phase one, processes each new input independently and quickly. Since the weights are baked in, no further calls to a large model or external service are needed.
This separation is powerful because it decouples the expensive understanding step from the cheap execution step. You pay the compilation cost once, and then enjoy fast, local, offline execution for every subsequent use.
## How the Architecture Works
The system employs a two-model architecture consisting of a **compiler** and an **interpreter**.
### The Compiler
A relatively large language model — fine-tuned specifically for this purpose — serves as the compiler. When given a natural language specification such as “Classify urgent emails,” the compiler generates two things:
– **A LoRA (Low-Rank Adaptation) adapter** — a small set of additional weight matrices that specialize a frozen base model for the specific task at hand. LoRA adapters are compact, typically a tiny fraction of the full model size, and can be swapped in and out efficiently.
– **A pseudo-program** — a structured, cleaned-up version of the task description paired with a handful of input/output examples. This is embedded directly into the interpreter’s prompt at runtime so the model knows exactly what behavior is expected.
### The Interpreter
The interpreter is a small, frozen language model — roughly 0.6 billion parameters — that serves as the runtime engine. It never changes during the process. What changes is which LoRA adapter is loaded onto it. Different tasks get different adapters, but they all share the same underlying base model.
When a new input arrives, the interpreter loads the adapter, receives the pseudo-program in its context, and produces the output — all locally, in milliseconds on modest hardware.
### Training the Compiler
The compiler is trained using triplets of data: a specification, an example input, and the desired output. During training, the compiler generates an adapter, attaches it to the frozen interpreter, and the combined system is optimized to produce the correct output. Gradients flow backward through the interpreter into the compiler, allowing the compiler to learn how to generate better adapters. Importantly, the interpreter’s base weights remain frozen throughout — the compiler learns to discover clever ways of reprogramming the same small model for vastly different tasks.
## Performance and Results
Researchers evaluated this approach on a synthetic benchmark called FuzzyBench, which covers a range of text functions including classification, extraction, parsing, and format conversion. Each task in the benchmark uses previously unseen specifications during testing, ensuring a fair evaluation of generalization.
The results are notable:
– The **0.6 billion parameter interpreter**, when equipped with a compiler-generated adapter, achieves **73.4% exact-match accuracy**. This outperforms direct prompting of a **32 billion parameter model**, which scores **68.7%** on the same tasks — despite being roughly 50 times larger.
– This demonstrates that a very small model, when properly specialized, can surpass a much larger general-purpose model on specific, well-defined tasks.
A follow-up technique called **Compile by Training** further improves performance. After the compiler generates an initial adapter, a brief fine-tuning step — roughly 100 gradient steps on teacher-synthesized examples — refines the adapter for the specific task. This process takes only about a minute in practice and pushes performance on a difficult subset of the benchmark up to **83.6% semantic accuracy**.
Both compilation modes produce portable programs that run entirely offline after the initial setup.
## Why This Matters
Several aspects of this approach point toward a genuinely transformative shift in how we think about AI-assisted software.
**Portability and privacy.** Because the final program runs on a CPU without any network calls, sensitive data never leaves the user’s machine. This is critical for healthcare, legal, financial, and personal applications where data privacy is non-negotiable.
**Composability.** Because neural programs are saved as compact files (the adapter weights plus the pseudo-program), they can be integrated into ordinary software pipelines, combined, version-controlled, and distributed just like any other software component.
**Efficiency.** Training or running a massive model for every single inference call is wasteful when the task doesn’t change. By compiling a specialized, lightweight program once and running it cheaply forever, this approach dramatically reduces compute costs at scale.
**Democratization.** A system that can run on a CPU makes powerful AI capabilities accessible on devices without expensive GPUs or constant cloud connectivity. This opens the door for deployment in embedded systems, mobile devices, and resource-constrained environments.
## Getting Started with the Approach
For practitioners interested in experimenting with this paradigm, a practical workflow looks like this:
1. **Define your task** in plain English, being as specific as possible about the inputs, outputs, and decision logic.
2. **Compile** the specification using the available tools to generate a neural program.
3. **Create a small hand-written validation set** to test the compiled function on a few examples.
4. **Inspect errors** and iterate on either the specification or try an enhanced compilation mode if results are unsatisfactory.
5. **Deploy** the resulting program locally and use it as part of your application.
The key recommendation from researchers is to treat the compilation step as part of your development cycle, not a one-time setup. Revising a natural language specification is far easier than rewriting code, and iterating on a spec lets you rapidly improve program behavior.
## Common Questions
**Can I host the compiler myself?**
Yes. The compiler model weights are publicly released, and you can run the compiler on your own GPU hardware. The local interpreter, however, is small enough to run on a CPU even without a GPU.
**What happens if the compiled program doesn’t work well?**
The recommended approach is to revise the natural language specification — add more detail, clarify edge cases, or provide additional examples in the pseudo-program. There is also an enhanced compilation mode that performs a brief fine-tuning pass, which significantly improves accuracy on difficult tasks.
**Is this limited to text classification tasks?**
No. While the benchmark and examples focus on text functions like classification, extraction, parsing, and format conversion, the underlying architecture is general-purpose. Any task that can be expressed as a function mapping inputs to outputs is, in principle, a candidate.
**How does the size of the interpreter model affect quality?**
The 0.6B interpreter represents a current balance between quality and efficiency. Smaller models would be faster but potentially less capable; larger models would be more powerful but require more resources at runtime. The architecture allows different interpreter sizes to be swapped in.
**What is the difference between the standard compiler and the “Compile by Training” variant?**
The standard compiler generates an adapter directly from the specification in seconds. Compile by Training adds a brief fine-tuning step after adapter generation, using synthesized examples to refine the adapter. This produces higher accuracy at the cost of roughly one minute of additional compute.
**Can these neural programs be combined or composed?**
Yes. Since each program is a self-contained unit with adapter weights and a pseudo-program, multiple programs can be chained together in a pipeline, used conditionally, or integrated into larger software systems just like any modular code component.
## Conclusion
The idea of compiling human-readable specifications into compact, local, reusable neural programs represents a genuinely compelling direction for AI research and application. It addresses several persistent pain points of current AI usage — dependency on cloud services, ongoing compute costs, privacy concerns, and the brittleness of prompt-based approaches — while remaining accessible and practical.
What makes this approach particularly exciting is its philosophical implication: large models can serve as tool builders, generating small, specialized programs that outlive any individual inference session. The vision of a future where you describe a function you need, receive back a small neural program, and integrate it into your own software is not far-fetched. It is actively being built.
As these systems mature, we can expect to see more sophisticated compilers, diverse interpreter architectures, and novel applications that we have not yet imagined. The boundary between “writing software” and “describing what software should do” is beginning to blur — and that is a development worth watching closely.
Thank you for reading
