



# The Hidden Killer in Deep Learning: How Silent Tensor Broadcasting Can Ruin Your Models
Machine learning practitioners spend countless hours tuning architectures, selecting hyperparameters, and engineering features. But there’s a sneaky bug lurking in the foundations of nearly every deep learning framework that can render all of that work meaningless — and it won’t make a single sound while doing so.
This bug has probably already sabotaged your projects without you ever knowing. It’s responsible for wasted GPU hours, mysterious training curves, and models that learn nothing useful despite appearing to converge perfectly. The worst part? Both PyTorch and TensorFlow will execute it without raising a single warning.
## How Broadcasting Became a Trap
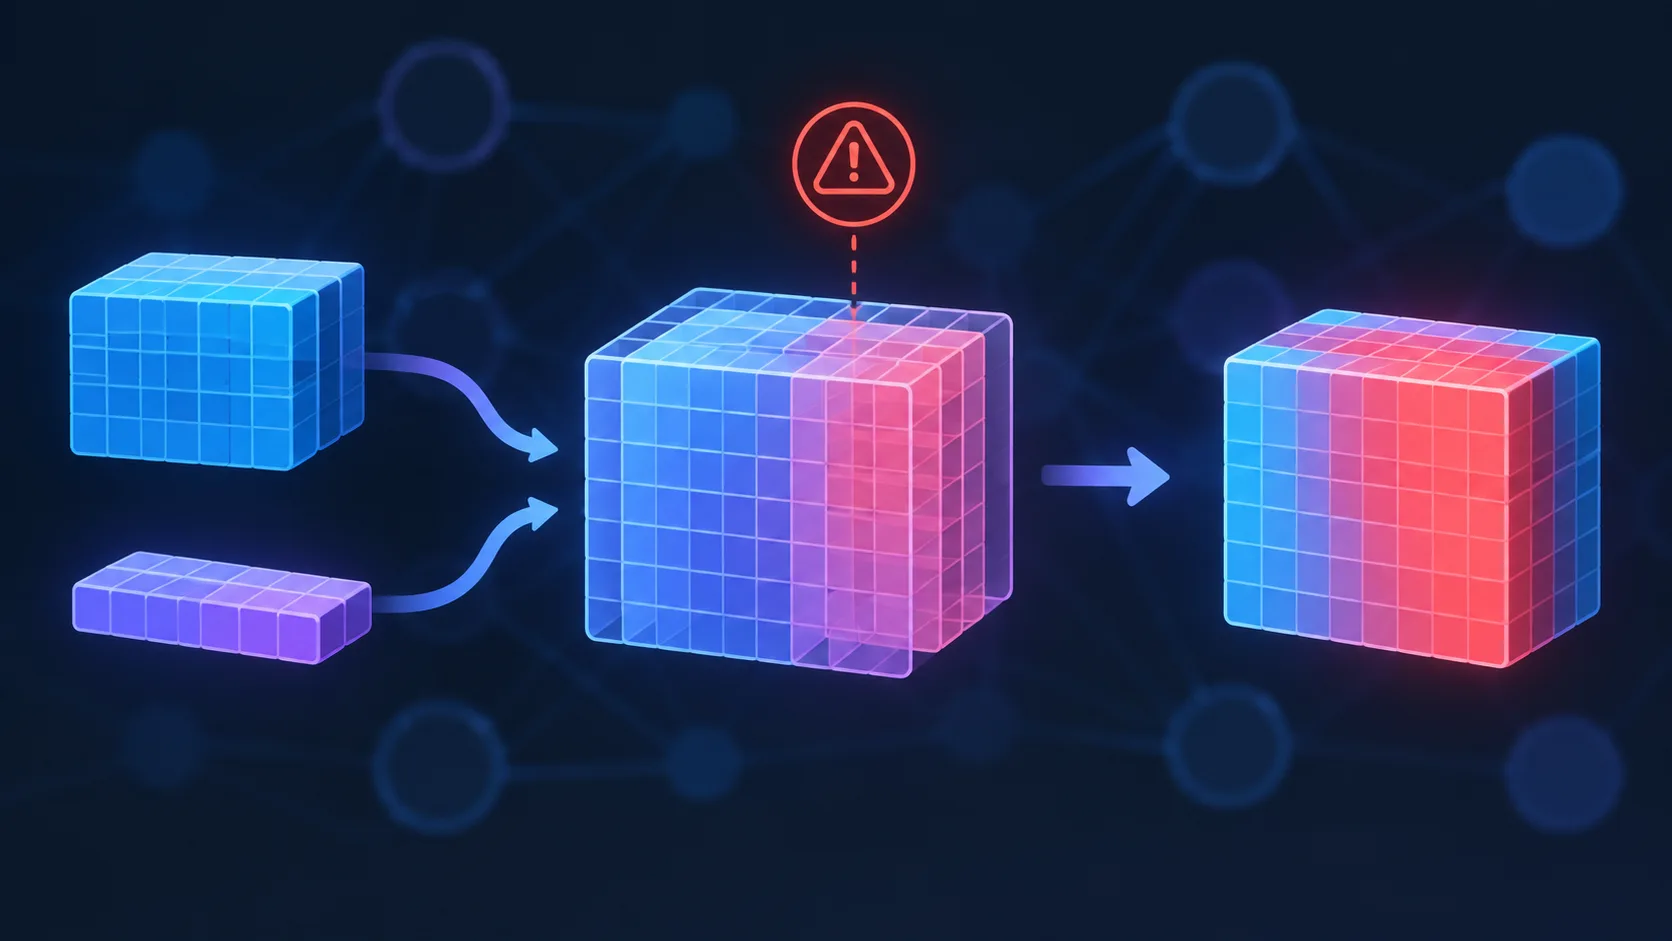
Most tensor libraries support a feature called broadcasting, which allows operations between tensors of different shapes. The idea is elegant and convenient: when two dimensions match, they align naturally. When one dimension has size 1, the framework stretches it to match the other tensor. Missing dimensions are treated as size 1. Only when none of these conditions are met does the framework finally raise an error.
This behavior is useful for common operations like adding a bias vector across every row of a batch. But the same flexibility that makes those operations simple also creates a dangerous pitfall: a tensor shaped `(N, 1)` and one shaped `(N,)` are considered compatible, even though one is a column vector and the other is flat. When you combine them, you don’t get the elementwise operation you intended — you get an `(N, N)` matrix where every pair of elements has been compared or combined.
The failure mode here is particularly insidious: the operation runs without any error. Loss decreases. Gradients flow backward. The training loop looks completely healthy. But the model is quietly optimizing toward something entirely different from what you asked it to learn.
## When Models Learn Nothing (But Loss Looks Perfect)
Consider a regression scenario where you have a model outputting predictions and a target tensor containing ground truth values. If your prediction tensor has shape `(N,)` — perhaps because you forgot to squeeze a final dimension after a linear layer — and your target has shape `(N, 1)`, the subtraction operation will broadcast into an `(N, N)` matrix.
Instead of computing the difference between each prediction and its corresponding target, the framework computes the difference between every prediction and every target. The loss value you’re minimizing becomes a sum over all pairwise differences, divided by `N²`. When you take the derivative with respect to any single prediction and set it to zero, every prediction converges to the same value: the average of all targets.
This means your model learns to ignore its input entirely and simply outputs the mean of the training targets every time. The loss drops quickly because collapsing to a constant is trivially easy to optimize. The training curve looks textbook-perfect. But the model has captured zero relationship between features and labels.
This exact failure pattern appears frequently in real projects, and it’s remarkably hard to diagnose because the symptoms look normal. The loss converges, the metrics look reasonable, and nothing triggers an alarm. Yet the model is fundamentally broken.
## Policy Gradients and the Credit Assignment Crisis
The consequences become even more severe in reinforcement learning, where each action in a sequence needs to be evaluated individually based on its own outcome. When computing policy gradient losses, you typically multiply the log probability of each action by its corresponding advantage estimate. If those two tensors have incompatible shapes due to broadcasting, the multiplication creates an `(N, N)` matrix instead of elementwise products.
After averaging over the batch, the gradient signal collapses to a single scalar applied uniformly to every action in the batch. Each action loses its individual advantage signal. The entire mechanism of “reinforce actions that worked, discourage actions that didn’t” disintegrates.
When advantages happen to be normalized to near zero mean, the broadcasted product produces an almost negligible policy gradient signal even though the individual advantage values contain meaningful information. The agent stops learning, but because RL training is inherently noisy and unstable, the symptoms — a plateauing reward curve — are easily misattributed to poor hyperparameters, bad reward engineering, or insufficient training time.
The actual fix in many cases is trivial: a single `.squeeze(-1)` operation on a value head output. But weeks of reward shaping and hyperparameter tuning could be wasted before anyone discovers the real problem.
## How to Protect Your Training Pipeline
The solution is straightforward, but it requires a deliberate habit: always verify that your tensors have the expected shapes before performing operations that are sensitive to elementwise alignment.
**Add explicit shape assertions.** A single line of code at the point where predictions and targets come together can catch broadcasting bugs instantly:
“`python
assert predictions.shape == targets.shape, f”Shape mismatch: {predictions.shape} vs {targets.shape}”
“`
This converts every silent broadcasting error into an immediate, loud failure at exactly the line that caused it.
**Be deliberate about squeezing.** Avoid using bare `.squeeze()` calls that remove all dimensions of size 1 indiscriminately. An accidental squeeze could drop your batch dimension if the batch size happens to be 1. Instead, use explicit dimension arguments like `.squeeze(-1)` to target only the dimension you intend to remove. Libraries like `einops` can help here too — their rearrangement operations fail loudly on shape mismatches rather than silently broadcasting.
**Write adversarial shape tests.** Go beyond testing that your loss function returns a reasonable number when given matching shapes. Write tests that deliberately feed in mismatched shapes and verify that your code raises an error rather than producing a value. This catches the bug before it ever reaches production training runs.
**Leverage static shape annotations.** When available, tools that let you annotate expected tensor shapes can catch dimension mismatches through static analysis or runtime checks before the offending tensors ever reach an operation that would broadcast them silently.
**Debug NaN failures systematically.** When your loss suddenly becomes NaN, resist the urge to immediately lower the learning rate or increase gradient clipping. Instead, inspect intermediate activations to find the first tensor in the forward pass that contains a NaN value. This will often lead you directly to the shape mismatch or masking bug that caused it.
## Frequently Asked Questions
**Q: Why don’t PyTorch and TensorFlow raise errors for these shape mismatches?**
Both frameworks intentionally support broadcasting as a design feature. The philosophy is that it’s better to be permissive and let users perform operations that “work” mathematically, even when the result might not be what was intended. The trade-off is that subtle bugs can survive undetected because nothing fails explicitly.
**Q: How can I tell if my model has been affected by silent broadcasting?**
The most telling sign is a model that converges quickly but produces outputs that are constant or near-constant regardless of input. For regression tasks, check if your predictions are all close to the mean of your target values. For classification, verify that the output distribution doesn’t change across different inputs. For RL, compare your policy gradient magnitudes against what you’d expect from per-sample advantage signals.
**Q: Are there other places where silent broadcasting causes problems besides loss computation?**
Yes. Masking operations are another common site of broadcasting bugs. When applying attention masks or padding masks, a shape mismatch can cause the mask to be applied incorrectly across all positions rather than just the intended ones. Any place where you combine a batched tensor with a per-sample or per-position tensor requires careful shape verification.
**Q: Is this bug more common in PyTorch or TensorFlow?**
Both frameworks exhibit the same broadcasting behavior because it’s defined by the underlying tensor semantics, not by any particular framework. The bug appears equally in both, though TensorFlow’s eager mode and PyTorch’s dynamic computation graph make it equally invisible in either environment.
**Q: Can static analysis tools catch these bugs before runtime?**
Some advanced tools can, but they’re not yet widespread in typical deep learning workflows. Shape annotations through libraries like `jaxtyping` or `torchtyping` can catch many broadcasting mismatches, but they require adopting additional type-checking infrastructure. The simplest and most universally applicable defense remains explicit shape assertions at the boundaries of your computation.
## Final Thoughts
Silent broadcasting is one of those bugs that is so deeply embedded in the design of modern tensor libraries that most practitioners never learn about it until they’ve already lost significant compute resources to it. The good news is that preventing it doesn’t require any complex tools or elaborate testing infrastructure — just the discipline to check that your tensor shapes match at the critical points in your training pipeline.
Add shape assertions. Be explicit about dimension manipulation. Test edge cases deliberately. These small habits can save you from weeks of debugging mysterious training behavior and thousands of dollars in wasted GPU time.
Thank you for reading
