



**Building a Resilient IoT Infrastructure Stack: From Physical Networks to Distributed Systems**
The Internet of Things has matured far beyond a simple collection of sensors. It now represents a comprehensive infrastructure stack stretching from the physical network connecting devices to distributed, cloud-native backend systems. With global connected device counts projected to soar into the tens of billions in the coming years, the sheer scale of this ecosystem underscores a critical truth: the value of any IoT deployment depends entirely on the infrastructure decisions made beneath it.
**The Physical Layer: Networking as the Bedrock**
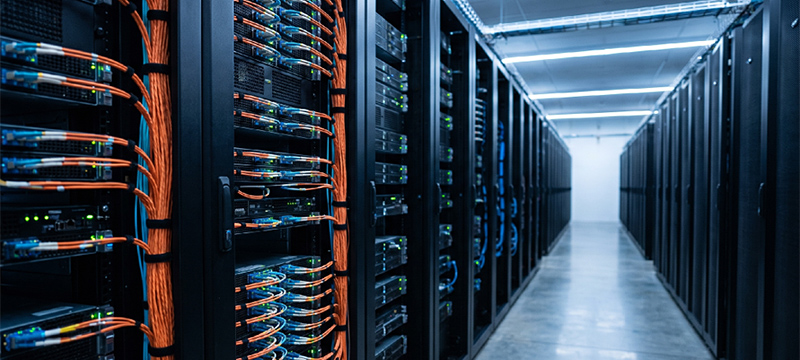
The foundation of any IoT deployment is the physical network. Connectivity failures remain the most common reason projects stall before they can scale. A significant majority of businesses testing IoT across sectors like agriculture, utilities, and logistics report experiencing network disruptions during rollout, stalling progress before the technology can even prove its worth. The financial impact of network downtime is staggering; for large enterprises, outages can cost thousands of dollars every single minute.
When dealing with thousands of endpoints transmitting continuous, time-sensitive data, an unreliable connection means missed safety alerts or corrupted telemetry that engineers won’t catch until it’s too late. The distinction between shared connections and dedicated fiber is vital here. Fiber offers symmetric speeds and high capacity, providing the consistent bandwidth and low latency required by mission-critical operations. Uptime guarantees vary wildly—a standard service tier might allow for nearly two days of downtime annually, whereas premium dedicated options offer near-perfect reliability with built-in repair windows. For enterprises running high-bandwidth or availability-sensitive operations, a dependable fiber connection is not a luxury; it is a prerequisite.
**The Data Journey: From Edge to Cloud**
Once the data leaves the device, it enters a complex journey. Modern architectures rarely send raw telemetry directly to a central data center. Instead, they push processing closer to the data source through edge nodes, filtering and aggregating information before forwarding a smaller, manageable payload to the cloud. This evolution has fundamentally changed what “backend infrastructure” means for an IoT deployment.
Rather than relying on monolithic servers, teams now deploy meshes of containerized microservices. These handle ingestion, analytics, and alerting across multiple regions simultaneously. Container orchestration has emerged as the industry standard for managing this complexity, providing the elasticity needed to spin up processing capacity as device fleets grow and scale it back down during quieter periods. This shift allows a pilot with a few hundred sensors to expand to thousands without requiring a complete system rebuild.
**The Operational Hurdle: Scaling Containerized Backends**
Elastic scaling solves one problem and introduces another. A containerized cluster processing IoT telemetry might run dozens or hundreds of pods across multiple nodes, each handling a slice of ingestion, transformation, or storage. That is a massive amount of moving parts, making the selection of the right management platform as critical as the network layer underneath it.
Managing autoscaling policies, multi-region failover, and container health across hundreds of nodes is the price of building a system that can grow with demand instead of collapsing at the next expansion. Enterprise leaders across manufacturing, logistics, and utilities are increasingly adopting these orchestration tools to run IoT at scale, moving away from legacy architectures that cannot keep pace with modern device demands.
**The Visibility Imperative: Observability in Distributed Systems**
The biggest tradeoff of this distributed approach is visibility. A single server failure is easy to spot, but a slow memory leak in one container out of hundreds quietly degrading performance across a cluster processing sensor data can go undetected for days. In an environment where downtime translates to severe financial loss, relying on generic dashboards or periodic manual checks is a direct path to operational risk.
Dedicated monitoring tools that provide granular, per-container visibility in real time are essential. They catch pods nearing their resource limits before they crash and flag nodes silently dropping packets, giving engineering teams the immediate insight they need. For a system processing continuous telemetry from thousands of devices, that visibility is what prevents the distributed backend from becoming a black box.
**The Unified Approach**
Reliable connectivity and real-time observability are two halves of the same coin. Connectivity gets data into the system; observability keeps the system running. If either fails, the other becomes ineffective. A perfectly monitored backend cannot function if the sensor fleet drops offline, just as a reliable network connection is useless if the backend infrastructure is silently failing.
Enterprises modernizing their data center and cloud strategies are increasingly building both layers in from the start rather than treating connectivity and observability as separate projects. Device fleets grow, backend architectures evolve, and the network and monitoring requirements that worked for a small pilot won’t necessarily hold at massive scale.
***
**FAQ**
**Q: Why do so many IoT projects experience connectivity failures during rollout?**
A: Deploying IoT often means spanning diverse environments—factory floors, remote well sites, or vast agricultural fields—where physical network conditions vary drastically. Unlike standard office setups, IoT must handle continuous, time-sensitive data streams across potentially vast distances, making network stability a common point of failure if the proper dedicated infrastructure isn’t in place.
**Q: How does edge computing improve IoT data flow?**
A: Edge computing processes data closer to where it is generated. By filtering and aggregating telemetry at the edge, only the most critical or reduced payload is sent to the cloud. This decreases bandwidth usage, lowers latency, and reduces the processing burden on centralized backend systems.
**Q: Why is container orchestration critical for IoT backends?**
A: IoT device fleets can grow rapidly, turning a pilot of hundreds of sensors into a deployment of thousands overnight. Container orchestration allows backend systems to scale elastically, spinning up new processing instances to handle increased data loads and scaling down during quieter periods, all without requiring a complete system rebuild.
**Q: What is the primary risk of operating an IoT backend without dedicated monitoring?**
A: In a distributed system with hundreds of microservices, failures are often silent. A resource exhaustion issue or a memory leak might not trigger an immediate system crash but will degrade performance over time, leading to delayed alerts or corrupted data. Without real-time, granular monitoring, these issues can escalate into costly outages before they are even noticed.
***
**Conclusion**
The success of IoT initiatives rarely hinges on the cleverness of the use case alone; it lives and dies at the infrastructure layer. Enterprises must invest equally in the physical network that moves data off devices and the observability tools that keep the backend processing that data reliably. As connected ecosystems continue to expand, the organizations that treat connectivity and monitoring as a unified, foundational priority will be the ones that scale successfully through the next decade, while those that treat them as afterthoughts will inevitably face their hardest lessons during the next major outage.
Thank you for reading
