



# How to Build a Document-Querying System That Understands Both Text and Images
Traditional search tools struggle with complex documents. If you feed a PDF full of financial charts, flowcharts, or data tables into a standard text-based system, it loses the formatting and skips the visuals entirely. You end up with an incomplete picture of the document, leading to inaccurate answers.
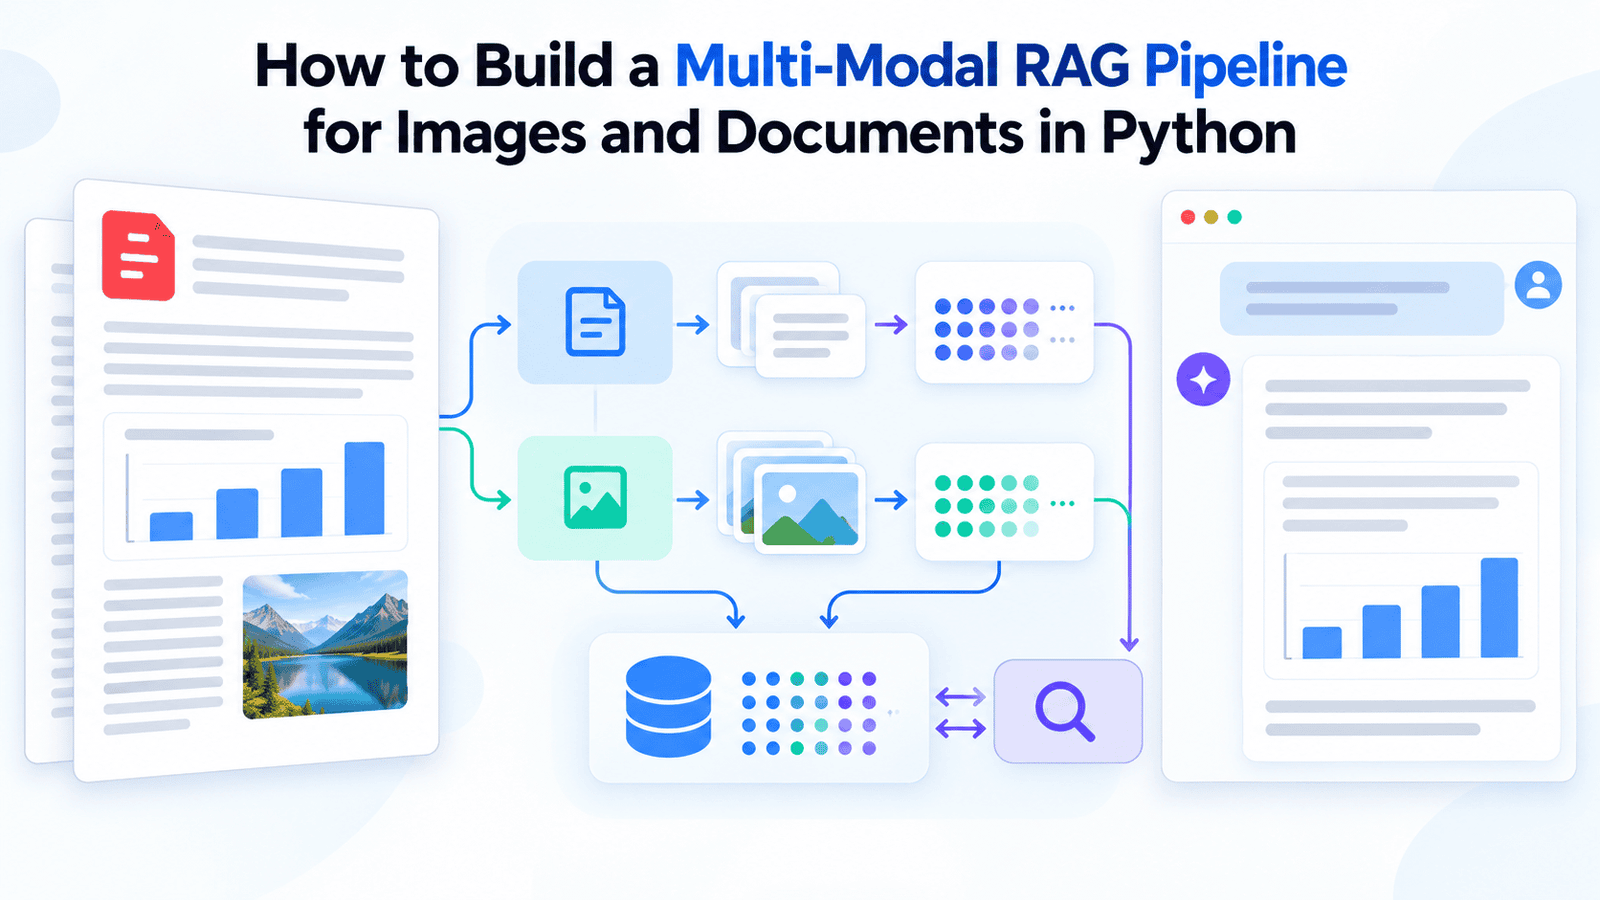
A multi-modal approach fixes this by treating images as first-class retrieval objects alongside text. Instead of ignoring visuals, the system learns to read them and bring them into the conversation when needed. In this guide, we will walk through building a document querying pipeline in Python that extracts, describes, stores, and retrieves both text and images to answer your questions.
## Getting Started
To build this system, you will need an OpenAI API key. The architecture relies on the `unstructured` library to parse documents, the OpenAI API for vision and embeddings, and `ChromaDB` to store everything efficiently. You will also need the `poppler-utils` system dependency installed, as it allows the Python PDF parser to extract images properly.
Before writing any logic, install the necessary Python packages and set your API key as an environment variable.
## Phase 1: Breaking Down the Document
The first step is to tear the document apart into its raw components. You do not want a flat wall of text; you need the paragraphs, tables, and images separated.
The parsing tool reads the PDF, identifies different element types, and classifies them accordingly. It saves extracted image files to a dedicated folder and groups text sections logically. Once the PDF is processed, you loop through the results to separate the text chunks from the image file paths. This separation is crucial because each type of content will be handled differently in the next steps.
## Phase 2: Making Images Searchable
A vector database cannot index a raw image file directly. It needs text to compare against your search query. Therefore, every extracted image must be converted into a dense, searchable summary.
This is where a vision model comes in. You feed each saved image to the model with a prompt asking for a detailed description suitable for a search system. The model returns a text summary that captures the essence of the visual. These summaries act as proxies for the actual images.
A quick tip for managing costs: if your document contains dozens of tiny icons or logos, consider filtering out images below a certain file size before sending them to the vision model. The cost of summarizing every tiny graphic adds up quickly.
## Phase 3: Setting Up the Dual-Store Memory
Standard retrieval systems keep everything in one place, but this multi-modal setup requires a dual-layer architecture. You use a `MultiVectorRetriever` which manages two distinct stores:
1. **A Vector Store:** This holds the embedded text chunks and the image summaries. It is used for fast, semantic similarity searches.
2. **A Document Store:** This holds the raw source content—the actual text and the actual image files. It is linked to the vector store through unique identifiers.
You generate a unique ID for every text chunk and image summary. The summaries and text go into the vector store for searching, while the original raw text and image paths are stored in the document store, tied to those same IDs. When a search finds a matching summary, the document store knows exactly which raw file to fetch.
## Phase 4: Querying with Multimodal Retrieval
Now the system is ready to answer questions. When you submit a query, the retriever embeds the question and searches across both the text and image summaries in the vector store.
Once the closest matches are found, the retrieval logic kicks in. It checks the metadata of each result: if the match points to an image, the system opens the raw file, reads it, and encodes it into a format the vision model can understand. If it points to text, it passes the text through as-is.
Finally, the system assembles a single prompt containing the retrieved text snippets, the raw encoded images, and the original question. This multimodal prompt is sent to the language model, which reasons across all the retrieved evidence—both words and visuals—before delivering a grounded final answer.
## Conclusion
Complex documents are rarely just walls of text. The most valuable insights often hide inside charts, diagrams, and embedded graphics. By building a pipeline that parses documents into separate text and image elements, generates searchable descriptions for visuals, and stores them in a dual-layer retrieval system, you can query documents just like a human would—reading the words and looking at the pictures simultaneously. This pattern scales well to research papers, product manuals, and financial reports. You can further enhance this setup by adding a re-ranking step to improve search precision or by experimenting with models that embed entire document pages as images directly.
## Frequently Asked Questions
**Why can’t standard RAG (Retrieval-Augmented Generation) handle images in PDFs?**
Standard RAG flattens PDFs into a plain text stream. In doing so, it destroys table formatting and completely skips over embedded images. Without the visuals, the system answers questions from an incomplete picture of the source material.
**Do I need a powerful GPU to run this pipeline?**
No. Because the architecture uses an API-driven approach for the heavy lifting—summarizing images, generating embeddings, and reasoning over the final prompt—you can run this entire system on standard hardware without a local GPU.
**What is the purpose of the document store?**
The vector store only holds the text summaries and embedded descriptions. It cannot store the raw image bytes or the full text blocks needed for the final answer. The document store acts as the raw content vault, holding the actual text and image files which are retrieved using the unique IDs that link back to the vector store matches.
**How do I reduce API costs when processing large document collections?**
Filtering out low-value images—like tiny logos, decorative icons, or watermarks—before they are sent to the summarization model is the most effective way to cut costs. You can also set a minimum file size threshold to skip irrelevant visuals automatically.
Thank you for reading
