



# Why Self-Driving Cars Need to Explain Their Decisions
The rise of autonomous vehicles has been one of the most ambitious technological undertakings of the past decade. Yet behind the wheel of every self-driving car lies a persistent challenge that has frustrated engineers, regulators, and the public alike: the so-called “black-box” problem. These vehicles make thousands of decisions per second, but when something goes wrong, there is often no clear way to trace the reasoning behind those choices. A new research effort aims to change that by building a system that makes autonomous driving decisions transparent, traceable, and understandable in real time.
## The Black-Box Problem in Autonomous Driving
Modern self-driving platforms depend heavily on deep neural networks trained on enormous datasets of real-world driving. These networks are remarkably effective at detecting objects, predicting trajectories, and planning maneuvers. But their internal logic is extraordinarily complex, composed of millions or even billions of weighted connections that do not map neatly onto concepts a human can readily understand.
This creates real-world difficulties. Imagine a self-driving car brakes suddenly on an empty highway. The passenger is startled. The safety operator is confused. With current systems, there is no immediate way to determine whether the vehicle detected a hazard that human eyes would miss, or whether the system simply made an error. This opacity undermines trust, complicates debugging, and makes it difficult for regulators to evaluate safety claims.
## A New Approach: Making AI Think in Human Terms
Researchers have proposed a novel architecture designed to bridge the gap between machine computation and human understanding. Rather than trying to reverse-engineer a decision after it has been made, the approach integrates interpretable reasoning directly into the vehicle’s decision-making pipeline.
The method translates the raw output of a neural network into a set of human-readable concepts — ideas like “Approaching Stopped Vehicle,” “Pedestrian Nearby,” or “Lane Departure Risk.” These concepts become the building blocks that the vehicle’s final planning system actually uses when choosing to brake, steer, or accelerate. Because the system acts on these concepts directly, the explanations are not after-the-fact guesses. They are causally linked to the decisions the vehicle takes.
This represents a significant departure from approaches that generate natural-language captions about what a system might have been doing. Those captions can sound plausible while being factually inaccurate. By grounding explanations in the actual concepts that drive behavior, the new method offers a more reliable window into the vehicle’s reasoning.
## From Simulation to Real Roads
Much of the prior work on explainable AI has been confined to computer simulations and controlled laboratory settings. The research team behind this new approach took a different path, deploying their system on an actual autonomous test vehicle operating alongside an experienced safety driver.
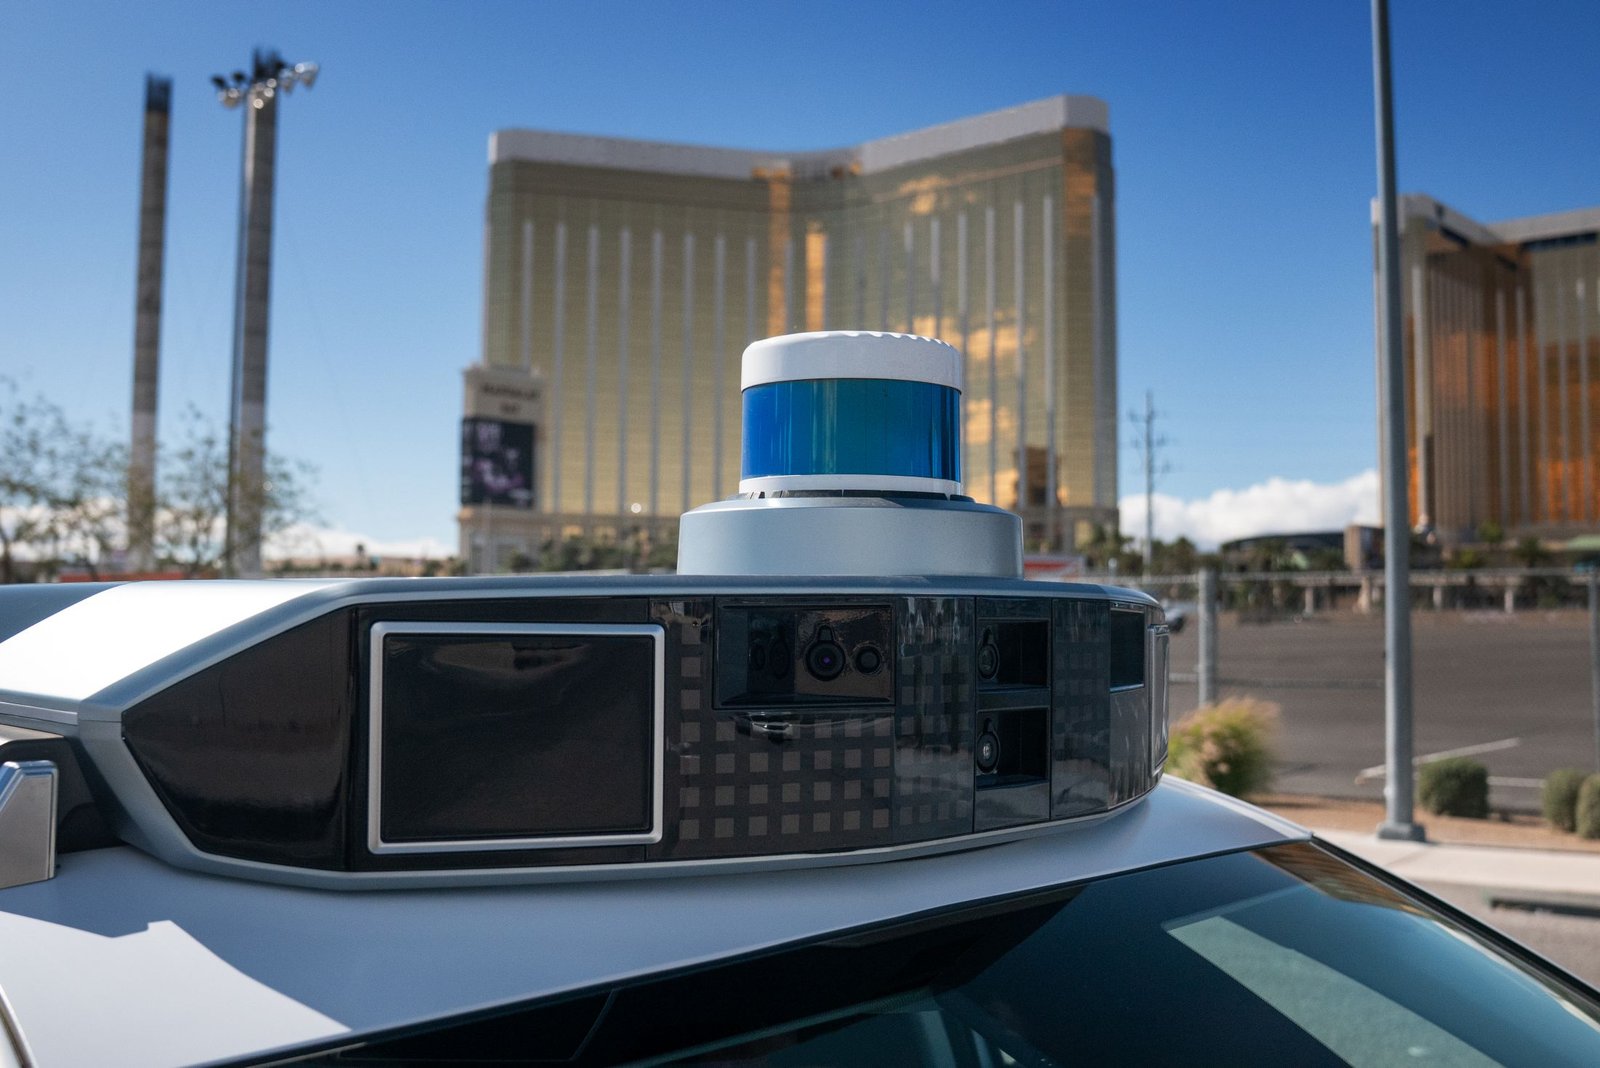
Data was collected on both a private test track and on public roads in and around Las Vegas, giving the system exposure to a wide variety of driving scenarios. The team used an earlier version of a deep-learning-based planning system that performed competitively but exhibited notable shortcomings — precisely the kind of issues that interpretability tools are meant to reveal.
Two specific incidents during testing illustrate the value of this transparency. In the first, the vehicle repeatedly stopped near a traffic cone. The safety driver assumed the cone itself was the trigger. When researchers removed the cone from the environment, the vehicle continued to stop in the same spot. The explainability system revealed that the planning module had essentially hallucinated a stopped vehicle ahead, a pattern inherited from its training data. Armed with this knowledge, the team was able to diagnose and address the root cause.
In the second incident, the vehicle detected a cyclist and stopped safely. However, the explainability layer revealed that the primary deep-learning planner was not actually the source of the braking decision. Instead, a separate safety backup system had intervened. The safety driver adjusted their behavior around cyclists accordingly, and subsequent analysis confirmed that the backup system’s involvement was a genuine concern that warranted closer attention.
## The Performance Trade-Off
Adding explainability layers to an AI system introduces additional computation and complexity. There is always a concern that this could degrade driving performance, reducing the speed or accuracy of decisions in safety-critical moments.
When the researchers benchmarked their system against established autonomous driving algorithms, the impact was minimal. The difference in overall driving capability was less than one percent. This suggests that meaningful transparency can be achieved without a significant compromise in the vehicle’s ability to drive safely and effectively.
Operationally, the value of this trade-off extends beyond academic benchmarks. A safety driver who can see that a particular stop was triggered by a hallucinated object or a backup system has a much clearer picture of what is happening and what to do next. This kind of situational awareness can be the difference between a routine test drive and a serious incident.
## Broader Implications for AI Governance
The push for explainability in autonomous vehicles is not just a technical exercise. It responds to growing pressure from regulators, insurers, and the general public for greater transparency in how AI systems operate. As autonomous driving technology expands into new cities, regions, and countries, the demand for auditable decision-making will only intensify.
Looking further ahead, the principles behind this research extend beyond passenger cars. Autonomous delivery drones, industrial robotics, and even systems used in robotic surgery all operate in safety-critical domains where understanding — and trusting — a machine’s reasoning is essential. If autonomous systems are going to earn the kind of trust required for widespread adoption, they will need to answer not just for what they do, but for why they do it.
The work represents a meaningful step toward a future in which artificial intelligence does not simply act, but communicates.
—
## Frequently Asked Questions
**What is the “black-box problem” in AI?**
The black-box problem refers to the difficulty of understanding how a complex system, such as a deep neural network, arrives at its decisions. The internal calculations are too intricate to inspect easily, making it hard to trace the reasoning behind a specific output or behavior.
**Why is explainability important for self-driving cars?**
Without explainability, it is difficult to diagnose errors, build public trust, or satisfy regulatory requirements. If a car brakes unexpectedly or makes an unsafe maneuver, engineers and safety operators need to know why so they can fix the root cause and prevent future incidents.
**How does CW-Net differ from other explainability approaches?**
CW-Net integrates human-readable concepts directly into the vehicle’s decision-making process rather than generating explanations after the fact. This means the explanations are causally faithful — they reflect the actual concepts the system used to make its choices — rather than being plausible but potentially inaccurate reconstructions.
**Was the system tested only in simulations?**
No. The system was deployed on a real autonomous vehicle operating on both private test tracks and public roads in Las Vegas, alongside a trained safety driver. This allowed the team to observe how the explainability layer performed in real-world conditions.
**Does adding explainability reduce driving performance?**
According to the research, the performance impact is negligible, with driving capability differing by less than one percent compared to leading autonomous driving algorithms. The trade-off between transparency and performance appears highly favorable.
**What other fields could benefit from this kind of explainable AI?**
Beyond autonomous vehicles, fields such as drone operations, robotic surgery, industrial automation, and any domain where AI systems make safety-critical decisions could benefit from real-time, causally faithful explanations of their behavior.
**What role do regulators play in this development?**
Regulators increasingly expect AI systems, especially those deployed in public spaces, to provide transparent and auditable decision-making. Tools like CW-Net could evolve from research projects into baseline requirements for autonomous system certification.
—
## Conclusion
The ability to understand why an autonomous system makes the decisions it does is no longer a luxury — it is a necessity. As self-driving technology moves closer to widespread deployment, the gap between machine intelligence and human trust must be closed. The approach explored in this research offers a practical, tested path forward, integrating transparency directly into the decision-making pipeline rather than treating it as an afterthought.
The Las Vegas test results demonstrate that meaningful explainability can be achieved in real time, on real roads, without sacrificing performance. These findings have implications that reach far beyond passenger vehicles, touching every domain where AI systems operate under safety-critical conditions.
The journey toward fully autonomous mobility is as much about trust as it is about technology. By giving self-driving systems the ability to explain themselves, researchers are helping to build the foundation on which that trust can be established.
Thank you for reading
