



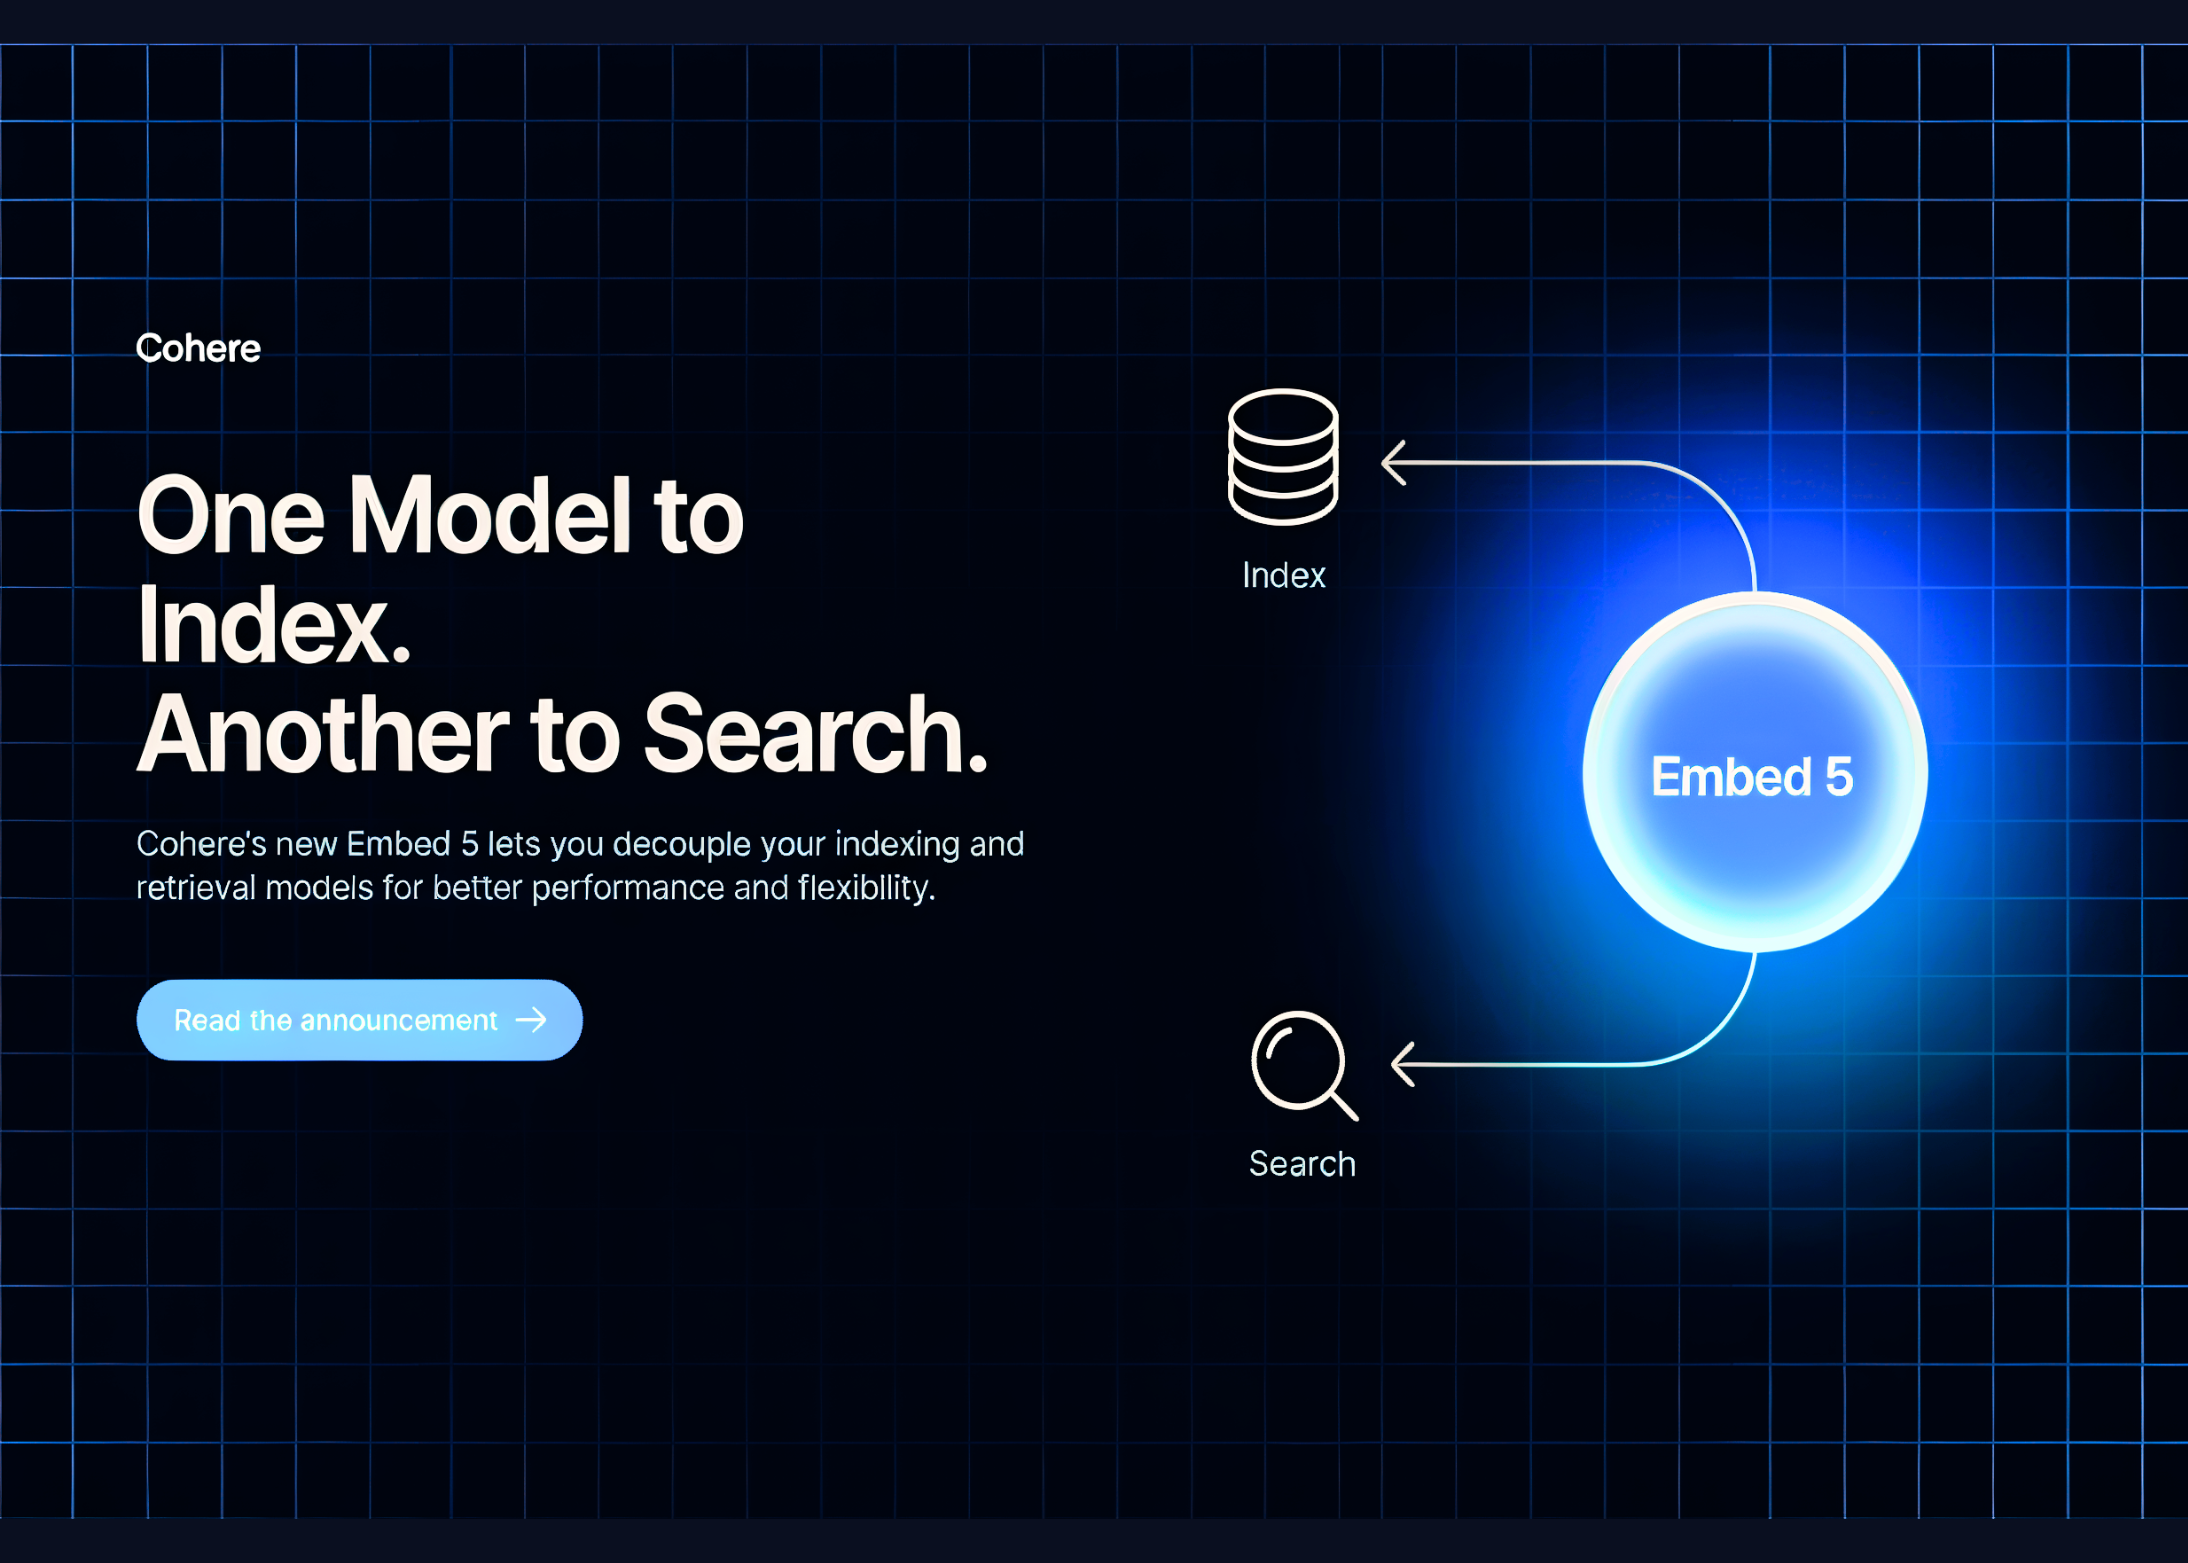
Cohere has launched Embed 5, a new family of embedding models explicitly built for demanding enterprise search, retrieval-augmented generation (RAG), and agentic retrieval tasks. The family comprises two tiers: Embed 5 Pro, which aims for the highest possible retrieval quality, and Embed 5 Fast, which is engineered to minimize latency and cost during the live query process. A defining architectural choice is that both tiers share a single embedding space, enabling users to index their corpus with the high-quality Pro model and then query that index using the low-latency Fast model without any compatibility issues or the need for re-indexing.
Both tiers are fully multimodal, accepting text, images, and fused text-plus-image inputs as a single vector. They support over 100 languages and feature a maximum context window of 128,000 tokens. This makes the models particularly effective for enterprise documents like scanned pages, slide decks, and technical schematics, where the ability to embed a page image directly or merge visual data with metadata prevents the loss of critical information that text extraction alone might miss.
The models are generally available on the Cohere API, Model Vault, Microsoft Azure Foundry, and Amazon SageMaker. Organizations requiring private cloud or on-premises solutions can deploy the models using vLLM, providing flexibility for sensitive data environments.
**Technical Specifications and Pricing**
The API model identifiers are `embed-v5.0-pro` and `embed-v5.0-fast`. They offer flexible output dimensions of 2048, 1536, 1024, 768, 512, or 256, with embeddings available in float, int8, or binary formats. Pro is priced at $0.12 per 1 million text tokens, while Fast costs $0.08 per 1 million text tokens. Image inputs cost $0.40 per 1 million tokens on both tiers.
**Performance and Throughput**
In terms of speed, Fast significantly outperforms Pro, processing 377.3 documents per second compared to Pro’s 159.7 documents per second. Cohere’s testing across 40 development datasets shows that a Pro-indexed corpus queried with Fast achieves a normalized score of 98.4 (where Pro querying Pro equals 100), while an all-Fast setup scores 96.6. This split is specifically designed to handle agentic workloads, where an agent may issue dozens of searches per task, making query latency a compounding bottleneck.
**Benchmark Performance**
On the ViDoRe V3 benchmark, Embed 5 Pro averages a score of 85.8, representing an 8.8-point gain over the previous Embed 4 iteration. Fast averages 84.5. These scores surpass Voyage 4 Large (83.7), Gemini Embedding 2 (83.2), and OpenAI’s text-embedding-3-large (75.5). In the finance sector, Pro ranks first on FinanceBench, FinQA, and ViDoRe V3 Finance, with Fast ranking second across all three.
It is worth noting that these benchmarks primarily use Cohere’s RCP-nDCG@10 metric, which evaluates reranking quality by reordering a fixed candidate set rather than first-stage recall. Independent replication of these results is still pending. Multilingual results were also mixed: Pro leads the European-language average, but Gemini Embedding 2 surpassed Pro in 9 out of 10 other tested languages, including Japanese, Arabic, Hindi, and Telugu.
**Storage Efficiency**
Embed 5 leverages Matryoshka representation learning combined with lower-precision outputs to drastically reduce storage requirements at scale. A 2048-dimensional float32 vector takes 8 KB of space, a 1024-dimensional int8 vector requires only 1 KB, and a 256-dimensional binary vector shrinks to just 32 bytes. Across 100 million chunks, raw storage drops from roughly 819 GB to 3.2 GB. Cohere recommends 1024-dimensional int8 as the default sweet spot, balancing near-full-precision quality with significant storage savings.
**Market Position**
Compared to competitors, Embed 5 offers a unique combination of shared embedding spaces across tiers, extensive context windows, and diverse output formats. While Voyage 4 Large also shares a space across its series, and Gemini Embedding 2 supports a wider array of input types like video and audio, Embed 5 balances high multimodal capability with competitive pricing and self-hosted options via vLLM, which are currently absent in OpenAI and Gemini’s standard offerings.
**FAQ**
**What is Cohere Embed 5?**
It is a dual-tiered, multimodal, and multilingual embedding model family designed for enterprise search, RAG, and agentic retrieval.
**How much does Embed 5 cost?**
Embed 5 Pro costs $0.12 per 1 million text tokens, and Embed 5 Fast costs $0.08 per 1 million text tokens. Both tiers charge $0.40 per 1 million image tokens.
**Can Pro and Fast embeddings be used together?**
Yes, they share a single embedding space, provided both the indexing and querying processes use the same output dimension. This allows you to index with Pro and query with Fast.
**Conclusion**
Cohere’s Embed 5 represents a significant step forward in retrieval-optimized embedding models. By introducing a fast, cost-effective query tier that shares a vector space with its high-quality Pro tier, the model family offers a practical and scalable solution for enterprise RAG systems. The combination of multimodal inputs, massive context windows, and extreme storage efficiency positions Embed 5 as a strong contender for large-scale industrial applications. Thank you for reading
